
We measured local safety models. The hard part was deciding what “works” means.
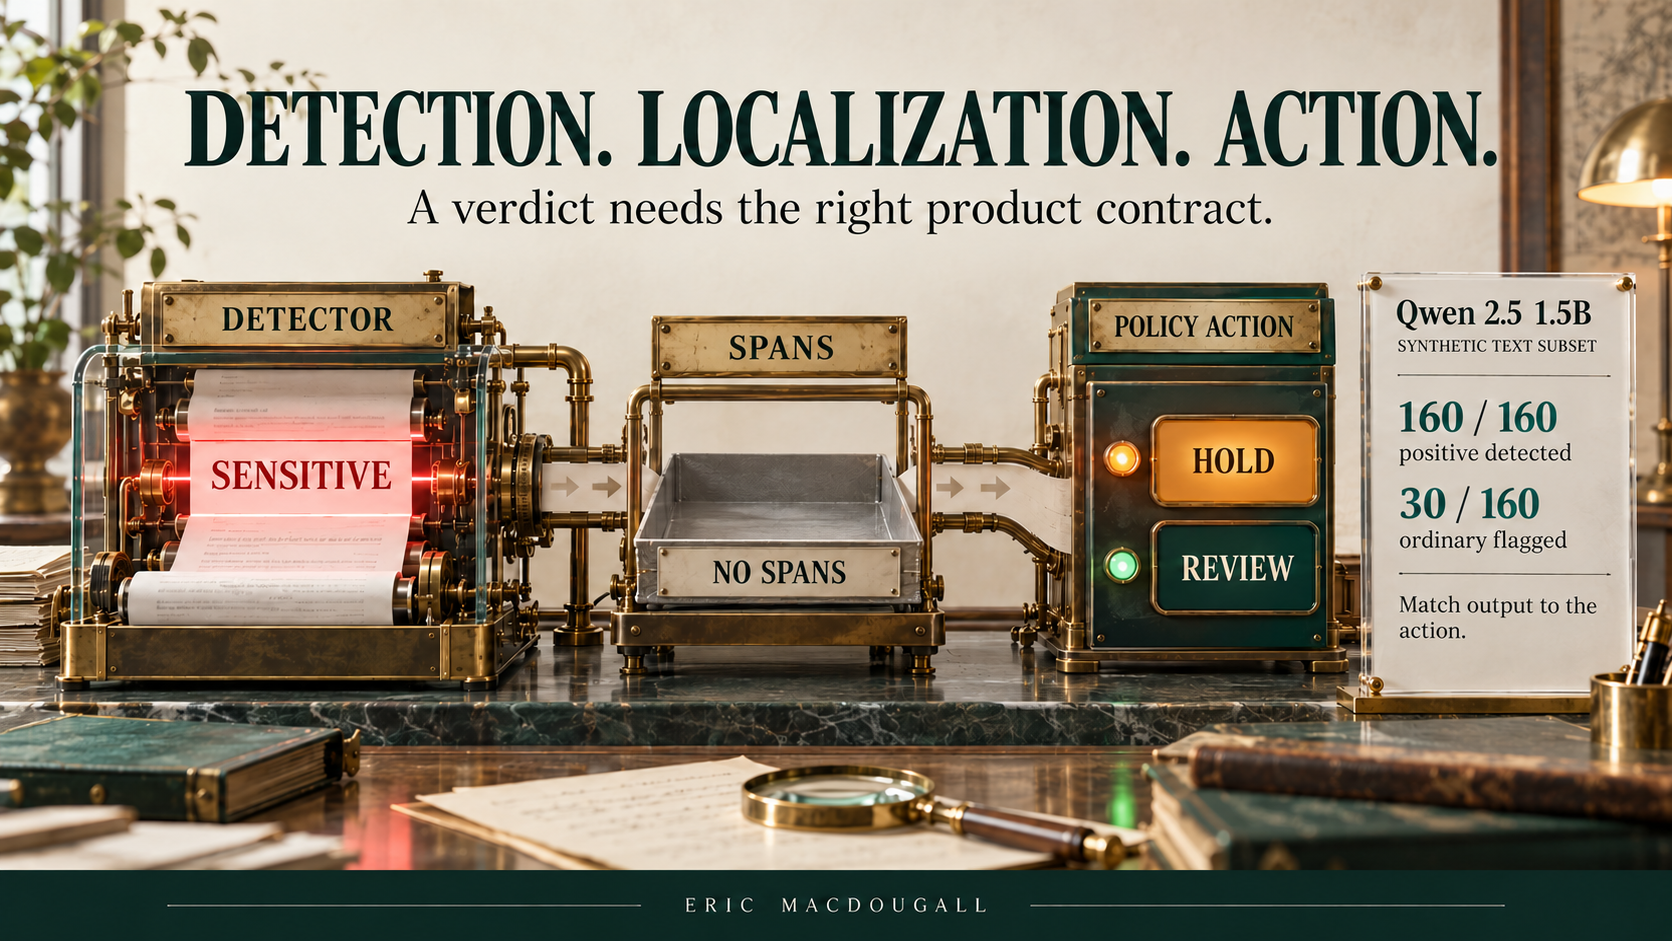
I got all 160 credential-bearing text examples flagged by our constrained Qwen 2.5 1.5B classifier. I also got 30 of 160 ordinary examples flagged and no redaction spans. Those results forced three separate engineering decisions.
I needed to separate detection, localization and the action the product could justify. One accuracy score would have hidden the difference between finding a message worth reviewing and safely removing its secret.
The experiment originated on 11 October 2026 and was reviewed during the following week's work. It produced 4,456 recorded CPU decisions across nine systems on a 602-row dataset. This article uses the retained report, benchmark code and recorded results. It is an exploratory comparison on synthetic, author-written and correlated examples. It is not a production validation or a universal ranking of security models.
The result was a more useful design framework: separate detection, localization and policy action; measure the deployment path; preserve uncertainty; and refuse to describe vendor-free inference as cost-free operation.
Three jobs hiding inside one “safety check”
Detection asks whether the text contains a credential or violates a configured policy. Localization asks which exact characters are sensitive. Policy action asks what the product should do with that evidence.
A boolean classifier can support a hold decision. It cannot establish that a redacted command no longer contains the secret. A span model can propose offsets. Those Unicode character offsets still need to refer to the original input text correctly and preserve the nonsecret material that the user needs.
Content safety introduces another distinction. A model trained to categorize harmful requests is answering a different question from a detector looking for a password. We evaluated Qwen 3Guard Gen 0.6B on safety descriptions using its native template. We did not repurpose its safety label as a password detector.
This separation should appear in the serving contract. If a system emits a positive verdict without verified spans, the result can be “hold for review.” It should not become “redaction successful” because a downstream function expects a clean string.
Illustrative interface, not the benchmark's production API:
class InspectionResult:
    verdict: str       # clear, sensitive, unsafe, uncertain
    spans: list        # offsets in the original inspected representation
    policy_revision: str
    adapter_revision: str

def choose_action(result):
    if result.verdict == "uncertain":
        return "hold"
    if result.verdict == "sensitive" and not result.spans:
        return "hold"  # Detection alone cannot authorize redaction.
    return "continue_with_separate_policy_checks"
Even verified spans do not authorize command execution or disclosure. The operation still needs the application's own permissions and destination policy.
What the corpus could and could not tell us
The dataset contained 320 credential text rows: 160 credential-bearing examples and 160 ordinary examples, spread across 16 families on each side. It also contained 120 safety rows built from 12 unsafe and 12 allowed base descriptions with five suffix variants each.
Command data combined 126 fresh synthetic examples with 36 surviving examples whose display oracle aligned exactly. Fourteen unalignable survivors were dropped. The requested original reviewer and named product corpora were unavailable, so this experiment cannot claim to have validated against them.
That history matters. The five variants of one safety description are correlated. The author wrote the examples. Some command gold came from an earlier implementation. These facts constrain what a confidence interval or aggregate score can mean. More rows do not automatically create more independent evidence.
There was no customer or child data. Credential strings were fake, including deliberately invalid provider-like tokens and documented examples. That made the exercise appropriate for local defensive testing, but it changed what some scanners were being asked to detect.
Coverage also stopped short of multilingual text, arbitrary encoding and splitting, confusable characters, long documents and multimodal inputs. Zero adapter errors and zero abstentions on the short recorded inputs do not settle those untested cases.
The inference protocol was part of the experiment
Gitleaks used default stdin JSON output. Detect-secrets used its default file-scan plugins without a verification filter. GLiNER received labels including password, API key, access token, secret key, private key and PIN, with a 0.5 threshold.
The general language models received separate fixed credential and safety prompts. The untrusted text was encoded in JSON. The decision used constrained native Yes/No output and a 0.5 threshold derived from the final-token comparison. These probabilities were uncalibrated.
An earlier six-message probe found strong letter-label bias in the small Qwen model. The final protocol replaced A/B labels with native Yes/No. The earlier run was retained as superseded rather than merged into the final headline.
That is a practical lesson about evaluating small models: the protocol can materially affect the task you think you measured. Label choices, chat templates, truncation, parsing and malformed-output behavior belong in the reproducibility record alongside the checkpoint name.
Qwen 3Guard used its official safety template and greedy generation. Safe was allowed; Unsafe and Controversial were flagged. This mapping is a product-policy choice. It is not a universal definition of what all applications must block.
The results that changed the decision
On the 320-row credential-text task, the Qwen 2.5 1.5B classifier detected 160 of 160 positives and falsely flagged 30 of 160 ordinary rows: 100% observed recall and 18.75% false-positive rate. Median warm latency was about 2.75 seconds. The recorded worker high-water mark was 9,198 MiB.
The smaller Qwen 2.5 0.5B classifier also detected all 160 positives, but falsely flagged 121 of 160 ordinary rows, about 75.6%. Its median was about 873 milliseconds. Faster execution came with a much heavier false-flag burden on this corpus.
Detect-secrets found 60 of 160 positives and flagged 10 of 160 ordinary rows. Its median was about 1.8 milliseconds. GLiNER small found 38 of 160 positives with no false flags among the 160 ordinary rows, at about 111 milliseconds. GLiNER PII found 116 positives and flagged 29 ordinary rows, at about 214 milliseconds.
These are different tradeoffs under different task fits. A low false-positive count alongside low recall does not establish a good release gate. High recall alongside frequent false flags can turn ordinary work into a review queue. Both the product action and the corpus composition determine which error is tolerable.
For the safety task, Qwen 3Guard detected all 60 unsafe rows and flagged one of 60 allowed rows, about 1.7%. Median warm latency was about 4.5 seconds, with a worker high-water mark of 4,676 MiB. This was promising evidence for that narrow synthetic task. It did not validate the full product safety taxonomy.
Why a scanner's zero is easy to misreport
Gitleaks recorded zero positive detections on the credential prose subset under its default rules. A sensational headline could turn that into “the scanner missed every secret.” That would misrepresent the test.
The corpus deliberately used fake or invalid strings and documented examples. A scanner designed around provider formats, entropy and example allowlists may intentionally suppress some of those cases. Natural-language passwords also differ from the live provider keys such a scanner is often deployed to find.
The honest statement is narrower: this default scanner configuration did not cover the credential-prose examples in this synthetic corpus. That helps us identify a product coverage gap. It does not estimate production recall on live vendor credentials.
The same discipline applies to the language models. Their strong result on author-written examples is evidence about that protocol and corpus. It is not a promise about adversarially split tokens in a long multilingual document.
Redaction exposed a different ranking
The fresh command subset had 119 secret-bearing rows. GLiNER PII produced exact positive spans on 36 of them, about 30.3%. It covered 68.9% of secret characters and also masked 908 nonsecret characters across that subset.
Those metrics describe different failure modes. Partial secret coverage can leave usable secret material behind. Nonsecret masking can damage a command or make a diagnostic display misleading. Exact span success asks for the complete correct answer on the positive row.
The experimental layered system achieved exact positive spans on 14 of 119 fresh secret-bearing commands, about 11.8%, with 12.6% secret-character coverage and 322 nonsecret characters masked. It could detect many more positive messages than it could safely redact.
The boolean-only general models had no redaction span capability. Their correct detection labels were not credited as redaction successes. That is a necessary boundary between the two tasks.
An aggregate exact-span score can be deceptive if it includes clean rows. A detector that emits nothing receives a correct empty span set on every clean example. In this corpus, Gitleaks could show 50% overall exact spans on credential text while detecting none of its 160 positive rows. Report positive-only span results so clean examples do not conceal failure on the work redaction is supposed to do.
Cascades need measured control flow
Our experimental cascade ran Gitleaks first, GLiNER small second and Qwen 1.5B if neither earlier stage detected a secret. An upstream positive could not be vetoed by a later stage. A model positive without spans meant hold. Oversize input or adapter failure meant abstain.
The cascade used actual staged calls. We did not estimate its median by adding three standalone medians. Different examples leave at different stages; short-circuit behavior and workload composition change the distribution.
This creates a design question that an accuracy table alone cannot answer. Is the fast stage selective enough to save meaningful downstream work? Does it preserve useful spans? What happens when it falsely flags a clean message? Does the final stage have enough capacity for the remaining traffic?
A cascade can improve coverage while failing to improve redaction, latency or user experience. Measure each objective on the actual route. Preserve the stage decisions so reviewers can see why a row took a particular path without retaining raw sensitive text unnecessarily.
Confidence did not rescue the policy
The Qwen 1.5B credential classifier's false-positive rate remained 18.75% when the threshold moved from 0.5 to 0.8 in the recorded analysis. The problematic predictions were confident enough to survive that change.
A token probability is a number from a particular inference protocol. It is not automatically a calibrated probability that the product's desired action is correct. Threshold tuning can be useful, but it needs separate evaluation and should be judged on both error rates and abstention behavior.
For an inline product, a false flag is an operational event. Somebody experiences a delay, review or refusal. The acceptable burden depends on the action and its recovery path. A detector used to suggest a local warning can tolerate a different error mix from one that blocks every assistant message.
Choose those states before celebrating the model's recall. Otherwise the model comparison quietly makes the product-policy decision for you.
CPU latency needs a deployment description
The experiment ran on a shared AMD EPYC 7702 virtual CPU host with 192 exposed cores and 377 GiB RAM. No GPU was found. Each model worker had four threads and handled one request at a time. Three independent systems could run concurrently, for twelve benchmark threads in that reproduction configuration.
These were warm request measurements, including tokenization and scanner process startup. They were not cold model-download times. The host was shared, so timings include that environment rather than a dedicated isolated server.
Peak worker RSS was a high-water mark including startup allocations. It was not simply model weights or steady-state serving memory. Child scanner memory was recorded separately, so a scanner's Python worker figure was not its complete process footprint.
That description is essential for transferring a result. “A small model takes four seconds” leaves out thread limits, queueing, batching, quantization, input length, model loading and competing work. Our measurements establish a baseline for this route, with these constraints. A resident optimized server might behave differently and would need its own run.
No vendor fee is a useful fact with a narrow meaning
The local runs incurred no vendor inference charge. That does not make them free. CPU reservation, memory, host rental, energy, maintenance and user waiting time remain costs. We did not have a defensible all-in host price for this comparison, so the report does not invent one.
For an illustrative capacity calculation, 1,000 sequential checks at roughly 2.75 seconds each occupy roughly 2,750 seconds of worker wall time. Reserving four threads over that interval is about 3.1 thread-hours. This is a reservation estimate from a median-based scenario, not measured CPU utilization or a throughput forecast.
The difference matters: a process can reserve threads without consuming all of them continuously. Actual serving economics also depend on arrival bursts, memory residency, utilization and the cost of the fallback or review action.
We did not run the billable comparison API because spending was outside the experiment's authorization. There is no measured cloud price-speed-quality baseline to place beside these local results. That empty cell is more useful than a fabricated comparison.
The deployment path still needed evaluation
The report's status was explicit: not ready for production replacement or complete acceptance. The suggested next step was a local resident service with a narrow typed result, a bounded queue, readiness checks, no raw-text logging and no automatic third-party fallback across the privacy boundary.
That service would still need a product corpus, independent evaluation, multilingual and long-input coverage, oversize and error tests, and tests of the real downstream action. It would need a clear policy for uncertain results and an owner for held work.
Shadow mode is useful here because it measures false flags on ordinary traffic without immediately converting every prediction into a user-facing block. It must still respect the data policy: shadow inspection is inspection, and logging every input would create another sensitive system.
A resident service also changes latency and memory behavior enough that it deserves a new benchmark. Reusing the exploratory worker measurements as a final capacity plan would skip the actual deployment question.
Give an abstention somewhere to go
An uncertain result needs an operational owner. A queue full of held work is not a completed safety rollout. Define who can review the item, what information that reviewer may see, how long the hold lasts and how the user can recover without bypassing the boundary.
Timeouts, oversized inputs and malformed adapter responses should be evaluated as product states, not removed from the denominator. Record which checks actually ran and whether any downstream effect occurred. That makes availability and safety measurable together instead of allowing one metric to improve by silently excluding difficult requests.
The decision framework I would reuse
Define the output the product needs: a warning, a block, a review state or verified redaction. Choose a corpus that represents that decision. Report positive and negative counts, not only percentages. Separate message detection from positive-only span quality and nonsecret damage.
Pin the inference protocol as carefully as the model. Measure the real cascade, error handling and resource footprint. Evaluate threshold changes on separate data. Keep uncertainty typed and preserve the application's own authorization checks.
Our most useful result was not a winning model name. It was a set of boundaries that prevented a promising detector score from becoming an unsupported redaction or safety claim.
Use the measurement table and three-job framework in your own evaluation. Before selecting a model, finish this sentence precisely: “When this system returns success, the product is entitled to do ___.” Then build the experiment that can prove or disprove that claim.
How this was verified
I used the retained experiment report, benchmark code and recorded outputs. The corpus is synthetic and correlated; latency is warm shared-host measurement. The local runs incurred no vendor inference fee, and I did not measure an all-in host price or a paid remote baseline. These results support the stated decisions on this corpus.