
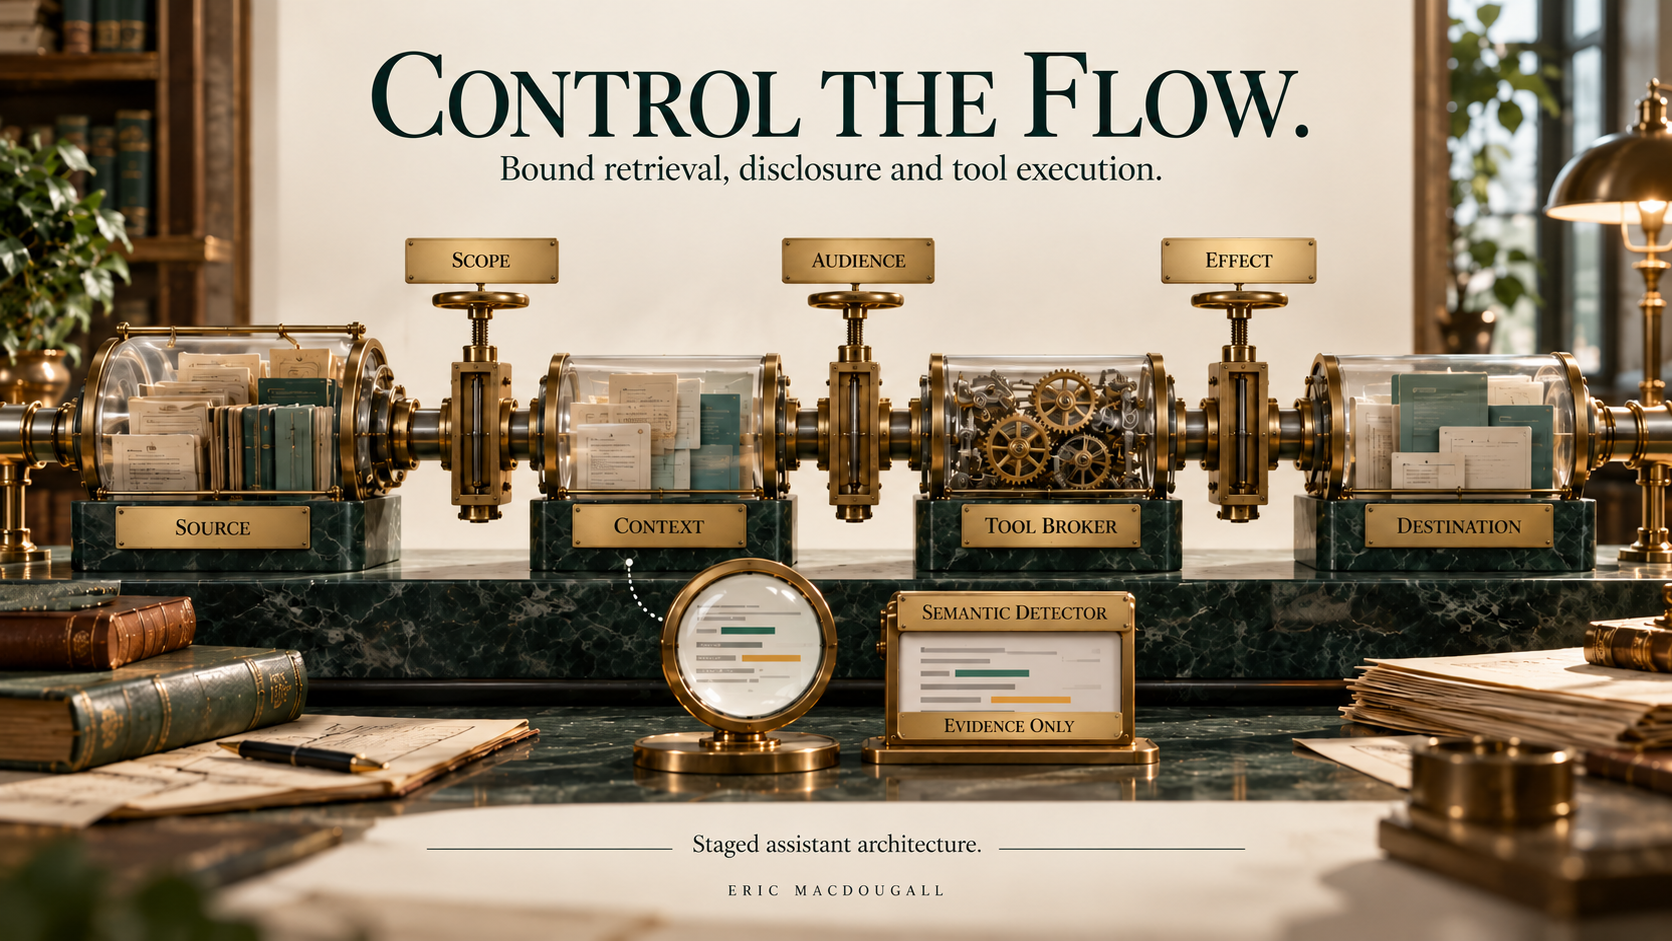
A semantic firewall needs an enforcement architecture
I design our assistant firewall around a concrete question: if the injection detector misses, which component can still refuse the unauthorized send?
I use this illustrative case to make the boundary concrete: an assistant reads a support ticket asking it to attach a confidential diagnostic report to an external message. The model understands the request, finds the report and proposes a plausible tool call. The example is a design exercise, not a reported production leak.
The security question is whether the system permits that flow. A classifier might notice the instruction. It might miss it. The architecture needs a meaningful answer in both cases.
This became the central decision in our October work on tool-using assistants: semantic detection supplies evidence about content; separate components own retrieval, disclosure, execution and network access. The useful firewall is the composition of those components, including their failure states and release order.
I am combining implemented boundary mechanisms with a broader assistant architecture that remains a proposal. That split lets me evaluate each control without claiming the full system is activated.
Start with the flow that matters
The illustrative ticket scenario has at least five decisions. May this requester read the report? May the assistant use it for this purpose? May the intended recipient receive it? Does the current approval cover this exact message and attachment? May the network connection reach its destination?
A semantic score settles none of those questions by itself. A text can be entirely benign and still belong to a different tenant. A request can be legitimate and still target an audience that lacks access. Conversely, security documentation can quote hostile instructions without trying to execute them.
That distinction changes the design exercise. Instead of beginning with a list of forbidden phrases, draw a graph: untrusted source, retrieved object, model context, proposed action, broker, external destination and rendered response. Mark which edge crosses an authority or confidentiality boundary. Assign an owner to each edge.
OWASP describes indirect prompt injection through external content and recommends measures including deterministic format validation and least privilege. That supports a layered threat model; it does not certify our implementation. See the primary guidance: https://genai.owasp.org/llmrisk/llm01-prompt-injection/.
Preserve provenance through useful transformations
Our proposed assistant plane separates published material, tenant settings, diagnostics, secrets and private coding traffic. It calls for tracking sensitivity, tenant, purpose, source and permitted destinations alongside objects and tool results.
The important part is how those properties survive change. Summarizing a confidential report does not make it public. Converting a private attachment into bullet points does not remove its audience restriction. A citation tells you where a statement came from; it grants no right to retrieve or disclose the source.
A conservative combination rule carries forward the restrictive requirements of contributing sources. If two sources have incompatible destinations, the combined answer may have no permitted external destination until a deliberate declassification step occurs. That step needs its own authority. Asking the model to declare the answer harmless is inadequate.
This gets difficult with freeform generation because exact token provenance is uncertain. We should acknowledge that uncertainty rather than manufacture precise lineage. A practical conservative design can label an entire derived artifact with the restrictions of the context used to generate it. That sacrifices some sharing flexibility while keeping the decision explainable.
Filter before retrieval and before disclosure. The first check limits what enters context. The second addresses the actual output and its actual audience. Neither makes the other redundant, particularly when a conversation changes participants or a background job runs after a membership change.
Separate inspection location from inspection quality
A hosted secret detector receives the secret before it can report one. That may be acceptable under a tenant's policy, or it may violate the reason for inspection.
Our assistant design therefore distinguishes local or customer-side egress checks from hosted inspection. The placement is a data-governance decision. Accuracy and latency then determine whether a particular model is useful inside that boundary.
Deterministic checks still earn their place: bounded input size, accepted MIME types, parsed URLs, schema validation and recognized credential patterns. They are predictable and often cheap. Their limitation is coverage. Recognizing a token format does not discover every password a person can invent.
Semantic detectors help with meaning and ambiguous intent. Their output should carry a policy-specific verdict, uncertainty and relevant evidence. It should not expand a tool grant or remove a source's confidentiality label. A classifier that says “allow” has answered its configured question, under its configured policy, on the bytes it received.
Compose checks around the bytes you will release
One of the most useful implementation details appears in our Go policy composition code. The Protect function evaluates current authority, executes ordered controls for a bounded buffered unit, revalidates configured grammars after transformations, then evaluates current authority again before returning bytes.
These are implementation observations, not a claim that every product route invokes this code. The source explicitly limits an allow decision to the policy and format controls it owns.
The pattern can be expressed with the following illustrative pseudocode. It omits adapters and persistence and is not a production library:
def protect_unit(unit, pin, target, current_authority):
    require_current_authority(current_authority, pin)
    data = bounded_private_copy(unit)
    grammars = resolve_pinned_grammars(pin, target)
    for stage in pin.ordered_stages(target):
        data = run_required_stage(stage, data)
        # Missing or failed required controls return a typed refusal.
    for grammar in grammars:
        grammar.validate(data)
    require_current_authority(current_authority, pin)
    return ProtectedUnit(data, policy_revision=pin.revision)
Revalidation matters because a later transformation can invalidate an earlier check. Imagine a valid structured tool argument that a redactor rewrites into malformed JSON. The grammar passed, but the released artifact is different. Checking the final bytes makes the composition's guarantee intelligible.
The second authority check addresses another kind of change: the world can move while inspection runs. A grant may expire or a policy may become ineligible during model inference. The code checks again at its own release boundary. A downstream side-effect adapter still needs to enforce its own current authority because a return from this function is not atomic with an external service accepting a write.
This is the architecture lesson: every guarantee has a scope, a protected object and a moment when it applies. A boolean named allowed conceals those details unless the API and callers preserve them.
Give the tool broker the questions it can actually answer
A tool broker should validate typed arguments against a narrow operation. It should resolve the requester and tenant from trusted execution context, rather than accept model-provided identities as fact. It should determine permitted objects and destinations from authoritative state.
For an outbound message, an approval should bind the material effect. In our code, outbound approval uses a canonical body hash with request body, raw query and effect facts; it derives recipients and relevant attachment or share state. A later guard compares the consumed approval digest and rejects a mismatch.
The subtle point is that human approval is also a composition problem. A person approving a preview does not automatically approve a different attachment or recipient assembled later. The execution check has to compare the approved effect with the actual effect at the point where the system can still refuse it.
For a credential-bearing integration, keep the credential out of general model context. A fixed adapter can inject a secret by reference into a configured destination. Restoring a secret into a model-chosen URL would combine sensitive data with attacker-influenced routing. A redaction stage upstream does not make that combination safe.
Model rendering and browser access are effects
The familiar tool-call path is only part of the source-to-sink graph. A generated image reference can cause a network request. A link unfurl can send information. Browser navigation, redirects and WebSocket upgrades can cross the same boundary through different handlers.
Our browser egress implementation resolves candidate addresses, checks them and pins an approved address to the connection for its supported HTTP, TLS and WebSocket paths. That is a concrete implementation pattern for reducing the gap between checking a hostname and connecting to an address. It is not evidence that every fetch path in the application uses the same enforcement.
The rendering side also needs a policy: which resource types may load, whether model-created links cause automatic requests, and which output is displayed as text rather than interpreted markup. Treat those as product behavior with tests. “The answer was safe” means little if its rendering fetched an attacker-controlled resource carrying private information.
A useful review technique is to close the obvious send-message tool and ask which other routes can still transmit bytes. That question often produces a better enforcement inventory than another round of prompt wording.
Required checks need a join before delivery
The enterprise-policy design proposes typed parallel actions with explicit dependencies, minimum input projections, output schemas, budgets and failure modes. The architectural issue is when their results become authoritative.
A required secret check cannot run asynchronously after the protected payload has already left. An optional analytics classifier can. Calling both branches “guardrails” hides a critical difference in timing.
For parallel checks, define a deterministic merge rule. Arrival order is an implementation detail, not an appropriate policy. A required timeout needs a typed result such as hold, block or error according to the pinned policy. It should not quietly remove the requirement from the join.
Streaming makes the boundary especially visible. Once bytes have been sent, later detection cannot recall them. If a control requires whole-document context, buffer the document or choose a smaller independently checkable release unit with a clearly narrower promise. Review the latency cost as part of that choice.
This is why the pipeline needs an explicit release owner. Somebody must know which checks are required, which bytes they checked, whether any transformation happened afterward and whether the authority is still valid.
Use semantic models where mistakes remain containable
The staged firewall plan puts enforceable action policy, audience flow and egress before semantic classifier expansion. It also proposes running classifiers in shadow mode until their false-positive behavior is understood on legitimate product content.
That is particularly relevant for a development or security assistant. Its ordinary work includes discussing system prompts, prompt injection and examples of malicious instructions. A filter that punishes those phrases can disable the very work users need the assistant to perform.
A second unrestricted language model reading the same hostile material does not automatically create isolation. A more constrained extractor can have a useful role if it returns narrow typed values and downstream code validates their meaning. Allowing arbitrary instructions to pass through a nominally quarantined model simply moves the trust problem.
CaMeL explores explicit separation of control and data flows and capabilities enforced at tool use. That research is useful context for this design direction. Our repositories should not inherit the paper's guarantees merely because our diagrams use similar language. The primary paper is https://arxiv.org/abs/2503.18813.
Measure the system's outcome, then the detector
A detector evaluation asks whether a label matches a corpus. An agent-security evaluation should also ask what happened in the system.
For the illustrative report-sharing scenario, useful outcome oracles include whether a message was created, whether the attachment identifier was disclosed, whether the destination received a request and whether an unauthorized recipient gained access. A transcript saying “I refused” cannot settle those questions.
Keep legitimate task completion in the evaluation. A system that refuses everything can suppress attack effects while being unusable. Report attack success and useful task success separately. Publish counts and denominators, category breakdowns, false-positive rates and uncertainty rather than one flattering aggregate percentage.
Separate a frozen evaluation set from adaptive attacks used during development. If the same examples drive repeated tuning and the final headline, the result measures fitting to those examples. Maintain a harder follow-up set and record which policy revision and model configuration produced each result.
Our 17 October document includes illustrative performance targets adapted from a reference design. They are not achieved results from our product. The defensible result of this work is a staged architecture and supporting code, together with a clearer acceptance experiment.
Test the controls when the classifier is wrong
An important acceptance experiment deliberately forces the detector to allow the injected document. The downstream broker should still refuse an unauthorized destination. That isolates the architectural boundary from the detector's success.
Then invert the condition. Supply legitimate security documentation and force a suspicious classification. Confirm the product enters the intended review or refusal state without accidentally executing an action or discarding the user's work. Failure handling is part of usability and security.
Other useful mutations are mechanical: change an approved recipient, expire a grant during inspection, remove a required classifier, transform a previously valid structure, change the DNS answer or place sensitive content in a rendered resource reference. Inspect the owning handler and destination state for each route.
These are proposed acceptance tests for the complete architecture, not a report that this whole matrix has passed. Each test needs an owner, fixture, expected effect and a negative control that proves the observation can detect the forbidden event.
Version the decision, not just the detector
A source-to-sink review also needs to survive a later configuration change. Record the policy revision, model adapter revision, tool schema and input representation used for each protected unit. A result from an old policy should not be silently reused under a stricter policy, and a cached classification should not cross tenants because the visible text happens to match.
The proposed enterprise action envelope includes request, action and attempt identity alongside policy and tool versions. That makes a delayed result attributable to the work that requested it. The release owner can reject an obsolete result instead of merging it into a newer attempt merely because it arrived last.
For investigation, retain the minimum evidence needed to explain the decision without automatically storing the private payload. Digests, revisions, stage outcomes and effect receipts can be useful, but they still need retention and access rules. Observability should help establish what happened without becoming a second uncontrolled route for the same information.
Choose the smallest enforcement system you can explain
A policy engine is useful when it improves ownership, versioning or expressiveness. A checked-in deterministic function may be enough for an early tool surface. Adding a distributed policy service before defining the protected flow can make the system harder to understand without strengthening its boundaries.
The same restraint applies to classifiers, caches and transcript stores. Every additional component introduces placement, retention, availability and versioning decisions. A semantic cache needs keys that respect tenant, source version and policy context. Raw transcript retention creates a sensitive store of its own. Neither is a free security improvement.
My decision rule is to start with one valuable workflow, enumerate its sources and sinks, and name the enforcement owner for each crossing. Preserve labels, check final transformed bytes, bind approvals to actual effects and join required checks before release. Add semantic detection where measured quality improves that system.
The next architecture review should trace one private source all the way to one real destination. Make the design explain what happens when the detector misses. That answer is the foundation of a useful semantic firewall.
How this was verified
This article draws on our 17 October staged firewall plan, the assistant and enterprise-policy designs reviewed on 18 October, and implementations of policy composition, outbound approval and browser egress. Those are different evidence classes. Several boundaries exist in code. The broader assistant architecture remains a proposal. We have not demonstrated universal prompt-injection resistance or activated every control described here.