
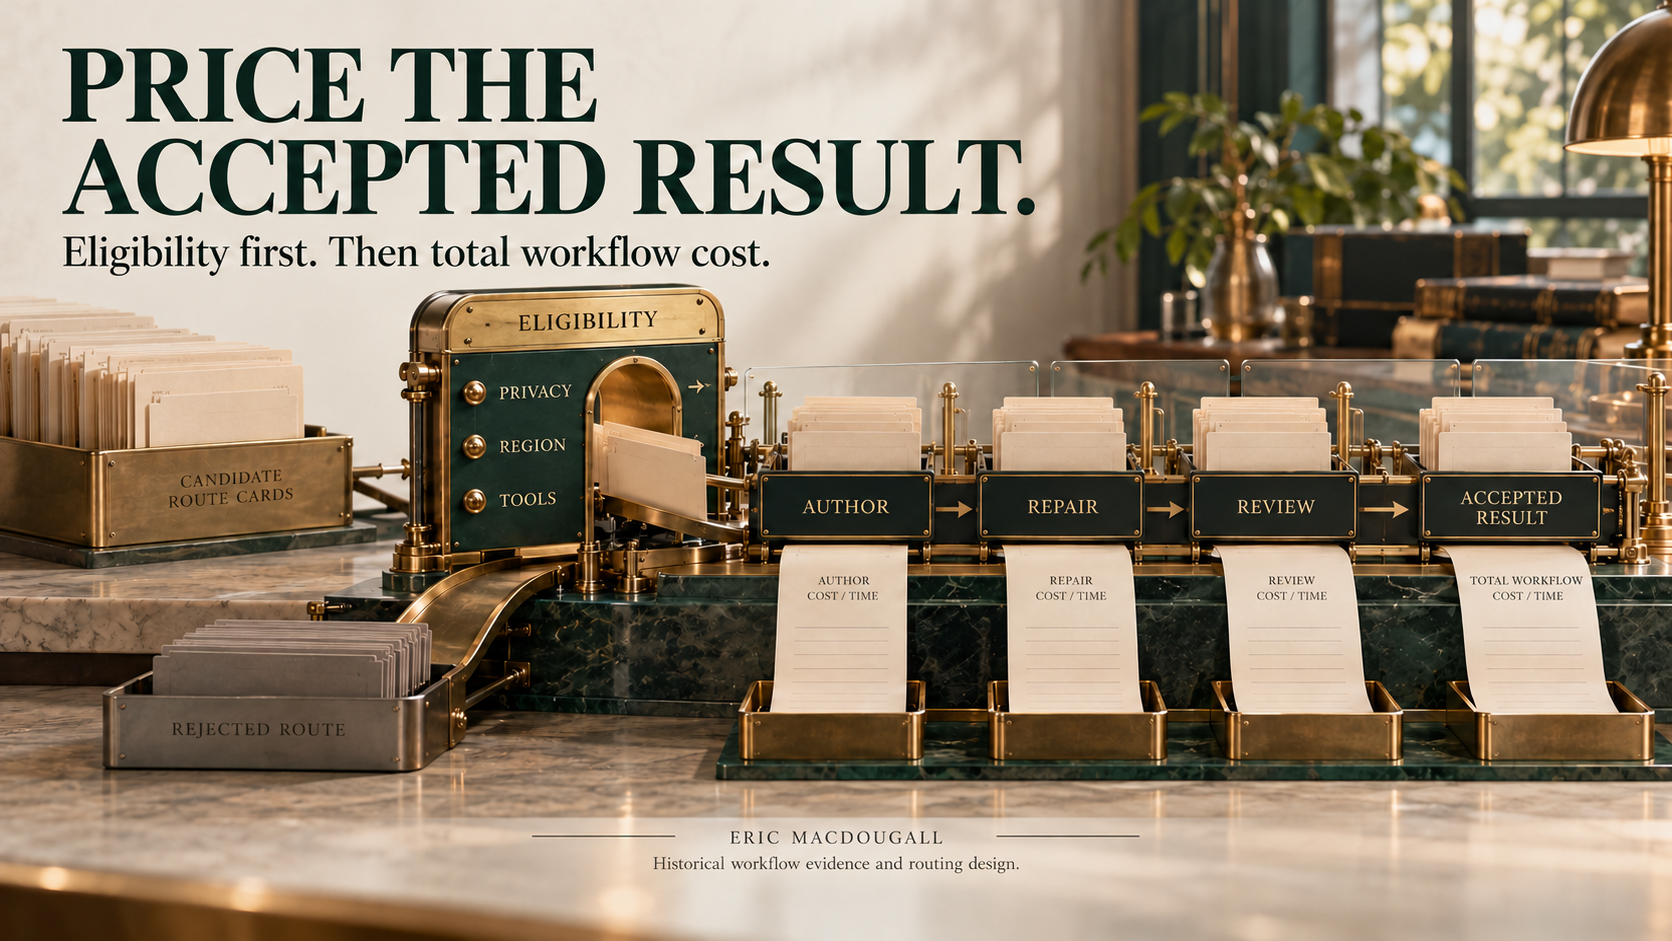
Route AI work by the cost of accepted outcomes
I evaluate the cost of an accepted result, including repair and review. A cheap first model call can start an expensive workflow, and a route with the wrong privacy or tool contract is ineligible regardless of price.
Those are two different decisions. First establish eligibility: privacy, region, authorization, tool semantics, commercial permission and required capability. Then compare the cost and latency of reaching an accepted result among eligible routes.
I used our October development logs to separate those decisions. We retained stage-level usage for authoring, repair, review and re-review; a benchmark corpus across task types; and routing designs that separate hard policy from soft optimization. The records did not support a defensible grand total of weekly cash expenditure. They did support a much better experiment than comparing the price of one draft.
Eligibility is a predicate, not a score
Suppose a task contains private source code and requires a tool operation with a specific authorization contract. A provider route that lacks the required data terms or cannot preserve that tool behavior is ineligible. Its low price should not compensate for that exclusion.
A weighted ranking that combines privacy, quality and cost can accidentally allow a sufficiently cheap route to win despite a hard requirement. The safer structure is a candidate filter followed by an optimizer.
Illustrative pseudocode, not an implemented router API:
eligible = [r for r in candidates if policy.permits(request, r)]
if not eligible:
    return Hold(reason="no_eligible_route", owner=policy.owner)
choice = rank(eligible, task_evidence, latency_budget, cost_budget)
return Decision(choice, policy_revision, price_revision, exclusions)
The hold needs an operational owner and a legitimate recovery path. A fallback that silently ignores the filter is a policy change, not availability engineering. A second model can introduce a different data path even when the user sees the same assistant persona.
Our runtime design names tenant scope, model capabilities, supplier permissions, region, retention, credential ownership, context and tool requirements, price ceilings and safety gates as eligibility inputs. Those are design requirements to verify on the actual route.
A route is more than a model name
The same displayed model can be reached through different providers, accounts, protocols or proxies. Those routes can differ in caching, quota, retention, tool formatting and error semantics.
The benchmark records include model aliases whose meaning belongs to the historical route. Do not silently replace them with today's public product labels and infer identical behavior. An experiment should pin requested model, resolved provider route, adapter version, effort, task, stage and relevant policy revision.
Tool behavior is especially important for agents. Does the adapter preserve system and user roles? Does it represent actual tool output honestly? Does a fallback retain current authority and the approval contract? Can the same tool schema and context fit? A provider that returns fluent text but changes these semantics is a different system.
Route eligibility therefore belongs in failure testing as well as initial selection. A primary route can pass all requirements while its emergency fallback bypasses them. Exercise the fallback with the same protected workflow, not only a prompt that asks it to say hello.
Count the complete path to acceptance
A useful engineering unit is an accepted outcome, with its review and repair costs included. The first draft is an intermediate artifact.
For a development task, the path may include planning, authoring, tool execution, review, repair, re-review, integration checks and an owner accepting the result. The owner may also spend time resolving ambiguity or discarding output that never reached the acceptance bar.
Define a cohort cost as the sum of all attributable work in that cohort divided by the number of accepted outcomes. Keep failed and abandoned attempts in the numerator. If the cohort produces no accepted outcome, report that state rather than manufacturing an inexpensive denominator.
The following is a measurement definition, not a fitted cost forecast:
cost per accepted outcome =
  all attributable measured cost in the cohort
  / accepted outcomes in the cohort
Do the same for qualified owner time and elapsed time, but do not add unlike units into an unexplained score. A route can be cheaper in supplier cost and worse in operator burden. The product has to choose the relevant tradeoff.
The retained logs showed why first-call accounting was weak
The 16 October analysis deduplicated mirrored host logs by filename, retaining the larger copy. It recorded 4,795 unique run files, of which 4,006 had usage attributed to a model. That retained population spans more than the requested week; it is a historical calibration corpus, not a weekly session census.
Its stage tables use a 48-hour start-time window ending near collection on 16 October. This narrower window is also distinct from the retained-log span. Every comparison needs to say which one it uses.
The report identified 63 shipped lane roots with an author run in the window. A lane root collapses related repair and rescope children using naming rules and a census. That is useful attribution, but it has limitations: names can collapse distinct work, and some roots marked shipped were already on main with only part of their cost visible in the window.
Those definitions make the aggregate reproducible and prevent a stronger claim than the data deserves. Shipped status in a workflow system is not automatically independent product acceptance, and partial-window costs are not complete lifetime costs.
The token totals were not comparable across engines
Claude-style results recorded input, cache read, cache write and output. Their total included all four. The Codex footer's tokens-used total in these logs omitted cached input under the collector's documented interpretation.
Adding the two totals produces a number, but not a common consumption measure. The report retained such mixed aggregates with warnings. They should not become a cross-engine efficiency ranking.
This is a measurement problem before it is a model-selection problem. Cache-heavy authoring can produce a large cache-inclusive token count without a proportionate supplier charge. A smaller reported total from another engine may omit the same category.
Use typed fields with an explicit measurement basis. Unknown is different from zero. If cache input is absent from one source, record it as unavailable rather than filling zero and claiming a normalized comparison.
An adapter migration can also change the meaning of a usage field while keeping its name. Version the usage schema and preserve the collector revision so later analysis does not silently combine different definitions.
Make missingness queryable
A useful observation schema carries operation and stage identity, route and adapter revision, usage basis, pricing basis and provenance. Give every measured field a value and a presence state. Zero output tokens, missing output usage and an adapter error are different observations.
The following is an illustrative analysis record, not a production event contract:
{
  "operation": "synthetic-op",
  "stage": "review",
  "usage_basis": "engine_footer_total",
  "reported_tokens": 12345,
  "cached_input_tokens": null,
  "price_basis": "unavailable",
  "measured_cost": null,
  "accepted_outcome": null
}
The example numbers are arbitrary. Its useful property is that uncertainty remains representable. A downstream aggregation should not coerce those null fields to zero or infer acceptance from a process exit code. Produce coverage counts beside any financial summary: how many attempts have usage, how many have a compatible price and how many have an independently observed outcome.
That lets a reviewer identify whether a cheaper-looking cohort is simply less instrumented. It also creates a concrete repair task for the telemetry pipeline without pretending the incomplete rows never ran.
Comparable stage data still needs context
Within the Claude-style Sonnet review cell in that 48-hour window, the aggregate contained 295 runs. The median cache-inclusive total was about 1.585 million tokens; mean output was about 12,975 tokens; the mean logged list-equivalent cost was about $0.664 per review run.
Those figures describe that historical cohort under its recorded basis. They do not establish a current review price, the cost of an independently accepted review or a comparable unit against an unpriced Codex row.
The same report had only one Opus first-author run in the narrow window, compared with 47 across the retained span. A precise median from a one-run cell is still a one-run observation. Comparing it to a much larger cohort does not remove task-selection and time-window differences.
Stages also differ in workload. A repair round may be assigned harder work precisely because a first attempt failed. A model doing more repair can look worse because of the work it inherited. Keep task family, stage, effort and selection history alongside the result.
Missing prices do not become free work
The report gives a mean of about $2.45 in Claude-run list-equivalent cost per shipped lane for the 63-root window cohort. It explicitly leaves Codex runs unpriced.
That is not “we ship a lane for $2.45.” It is a partial cost component on a historically defined cohort, with a list-price basis and incomplete route coverage.
The broader research also includes quota and subscription observations. A quota estimate, a list-equivalent amount, a prepaid subscription allocation and a cash invoice are different accounting objects. Treating them as interchangeable would make the result look precise while obscuring the business question.
A useful cost record states the basis, currency, pricing revision, covered stages and missing portions. For a cash-spend article, reconcile against billing evidence. For workload planning, token and quota measures may be useful if their semantics are explicit. Neither should quietly impersonate the other.
The honest missing-cost column is part of the result. Do not suppress expensive failures or empty runs because no usage block was returned.
Speed is a workflow distribution
Time to first draft, provider latency and time to accepted result measure different things. A quick draft followed by several repair and review rounds can produce a long tail that an inference median conceals.
Measure elapsed completion time and stage timings on the actual workflow. Preserve queue wait, quota denial, provider failure and owner intervention separately. Parallel work requires care: summing branch durations measures resource time, while the critical path determines elapsed time.
The retained benchmark has historical task timings that can screen route and effort combinations. It does not, by itself, establish owner-time savings or end-to-end shipping speed. Small tasks with a known grader differ from integrated work with review and deployment constraints.
Repeated attempts also change the distribution. Report how many operations reach acceptance within the chosen budget and deadline, plus how much work remains unresolved. Looking only at successful runs can reward a route that abandons difficult cases quickly.
Quota is part of capacity, not just price
A route may have a good list price and no available capacity when the workflow needs it. Shared account quotas, concurrency grants and delayed resets can dominate availability.
The runtime design proposes coordinating hard spend and concurrency authority while treating health and observed latency as softer signals. A disconnected worker should not independently assume it owns the entire supplier allowance.
Bounded grants need an owner, expiry and maximum allocation. Reclaiming an unreachable holder's grant requires evidence that it cannot also spend it, or an explicit policy consistent with the grant's expiration semantics. A stale permission cache is not unlimited authority.
Do not turn this into a complicated optimizer before measuring demand. A deterministic route order with clear eligibility, bounded concurrency and an honest no-capacity state can be easier to operate than a learned ranker whose decisions cannot be reproduced.
Fallback is another effect path
A provider failure does not automatically authorize another call. If acceptance of the first inference is ambiguous, a fallback can create another liability and a different answer. The runtime's initial contract disallows automatic resubmission after dispatch and requires reconciliation instead.
Before dispatch, eligible fallback may be possible under the specific admission contract. After dispatch, the operation state and provider evidence determine the next step. A generic SDK retry or model failover loop must not silently override that distinction.
Even a permitted fallback needs semantic parity: tool protocol, roles, authorization, privacy and cost reporting. The firewall plan explicitly calls for failover evaluation across those properties. That is a design requirement, not evidence all routes already pass.
Treat failover as an experiment with observable calls. Which route actually received the payload? Which credential was used? Did an unauthorized provider see private context? How many supplier acceptances occurred? A successful final sentence cannot answer those questions.
Keep routing policy fresh enough to mean something
The proposed runtime separates immutable route and price snapshots from current safety restrictions. An attempt pins its relevant versions for explanation and accounting. Soft observations can decay; revoked rights cannot remain valid indefinitely because a ranking cache is convenient.
A useful route decision record includes candidate exclusions, policy and price revisions, feature age, selected account or route, selection reason and bounded retry budget. It should explain the decision without storing the private prompt in every telemetry system.
Rollback needs the same care. Reverting a ranking experiment should not resurrect a revoked credential or region permission. Safety authority and ordinary ranking configuration have different monotonicity requirements.
These are proposed coherence controls. Their acceptance experiment needs disconnected gateways, expired permissions, stale feature data and an unchanged deterministic baseline. A signed snapshot file existing on disk does not prove the runtime enforces its expiry.
Build an experiment that can change the decision
Choose a task cohort with a fixed acceptance contract. Record route, model alias, effort, stage, context policy, tool adapter, input family, measured usage basis, elapsed time and owner interventions. Link author, repair and review work to a durable operation identity.
Use comparable task assignments where possible. Historical routing is selected by prior policy: harder tasks may have been sent to a stronger route, and quota exhaustion may have changed the remaining cohort. A naive average can confuse assignment policy with model quality.
Evaluate a new ranker on a temporal holdout and in shadow mode against a deterministic baseline. Exploration must remain inside the eligible set and an explicitly approved cost and risk budget. Offline replay of old decisions is useful analysis, not realized savings.
Before rollout, state what would reverse the choice: acceptance degradation, a worse repair tail, owner-time increase, quota pressure or a changed privacy requirement. The owner should be able to explain the replacement trigger without retraining the ranker to discover it.
The routing objective worth keeping
Start with eligibility. Compare complete accepted-work paths on compatible measurements. Preserve missing costs, thin cohorts and ambiguous outcomes. Treat fallback and telemetry as routes with their own controls.
The result may be a stage-specific mix rather than one universal model winner. That is a hypothesis to test with comparable cohorts, not a conclusion guaranteed by a small benchmark.
Use the full package's route matrix and measurement schema to review one real workflow. Ask which routes are allowed, which evidence supports their task quality and what the entire accepted outcome costs. Those questions survive the next model release far better than a first-call price ranking.
Revisit that evidence whenever the route changes.
How this was verified
This article uses the retained 16 October lane-cost analysis, its JSON aggregates, historical benchmark records and proposed runtime routing contracts. Model and route names are historical labels, not current product recommendations. Reported list-equivalent costs are not invoices. Proposed routing controls are not presented as fully integrated infrastructure.