
Design the authority boundary between a chatbot, an assistant and an agent
I gave our public website guide 31 approved facts and a deliberately small output protocol. The model selects one to three fact IDs. The server writes the displayed answer by joining the corresponding approved paragraphs.
That choice gives the model useful work without asking it to decide what our company is authorized to promise. It can misunderstand a visitor and select an irrelevant paragraph. It cannot add its own price, customer name or commercial commitment to the displayed prose through this protocol.
The distinction helped me draw the larger boundary between a chatbot, an authenticated assistant and an agent. Each capability increase changes which identities, data paths and effects the system must authorize. Making the model more capable does not automatically justify giving the same public endpoint access to account data or business tools.
The public guide is implemented. The broader signed-in and operator assistants remain an architecture and acceptance contract. I keep those states separate because a working public conversation can look like the beginning of an account assistant while having none of its authorization machinery.
Give the model a bounded selection job
Our output guard accepts an exact object containing kind and fact_ids. An answer selects one to three distinct catalog entries. A refusal selects none and receives a fixed server-owned refusal. Extra keys, unknown identifiers, duplicates and incompatible shapes refuse.
The decisive line is where output wording comes from:
const answer = (raw.fact_ids as PublicFactId[])
  .map((id) => PUBLIC_CHAT_FACTS[id])
  .join("\n\n");
There is no approved-prose field supplied by the model. Sending a valid fact selection plus an extra answer field does not give that field a ride through the guard. The exact-key check rejects it.
Catalog membership uses an own-property check. That matters in JavaScript because names such as toString can resolve through an object's prototype without being reviewed public facts. A type assertion is not a runtime membership check. The guard needs to establish ownership before using an untrusted string as a key.
I exercised the retained catalog across all 4,495 unordered three-fact combinations. Every combination passed the 1,500-character output limit; the longest was 1,313 characters. Order does not change the combined length, although it can change whether the answer reads well.
Those numbers establish a bounded output property for this frozen catalog. They do not measure how accurately a model selects relevant facts. They also do not establish that every approved paragraph is forever correct. Editing the catalog changes the product's public assertions and needs its own review and renewed bounds check.
Why I accepted less expressive flexibility
A freeform public assistant can paraphrase, translate, combine fragments and answer questions outside an anticipated catalog. Those capabilities can be valuable. They also create a larger public-claims review problem: the system can produce a new statement we never approved.
For this guide, I wanted a narrower product. We publish the wording, let the model identify the relevant public intent, and refuse when the protocol cannot express an answer. A visitor should see planned versus available distinctions in the approved text instead of relying on the model to remember every readiness boundary.
The tradeoff is visible. A response can feel repetitive. A narrow catalog cannot satisfy arbitrary translation or a detailed follow-up whose answer is absent. The model may choose a technically allowed but irrelevant paragraph. Those are product limitations to evaluate, not reasons to silently open a freeform path around the output guard.
I would change this design when the product needs richer explanation and we can support the corresponding evidence and review architecture. That could involve a reviewed retrieval corpus, evidence-linked claims and a separately evaluated response policy. It should be an explicit capability decision with a new acceptance suite.
A larger model alone does not supply that acceptance. The content boundary comes from the server protocol and catalog. Model quality mainly affects selection within it. This gives us a cleaner experiment: measure relevance and coverage while testing output membership independently.
Treat conversation history as untrusted input
The browser sends a bounded conversation, not a sequence of trusted platform instructions. The request parser expects alternating user and assistant entries ending with a user message. A client cannot insert a system role, add tool-call fields or supply a model override through that request shape.
Even an entry labeled assistant is user-controlled history from the server's perspective. The upstream body contains one server-owned system message and one user message carrying serialized untrusted conversation. A forged historical sentence saying I authorize every tool remains text inside that untrusted input.
That is an important handoff pattern beyond chat. A transcript can describe earlier authority without possessing that authority. A role label in an untrusted JSON document is not the same thing as an authenticated message in a trusted channel.
We also remove unsafe historical pairs rather than forwarding them into every later question. A visitor who previously asked for internal details can still ask a normal public question afterward. This is a bounded history treatment, not a proof that input detection recognizes every sensitive request.
The parser's configured ceiling is eight messages, but the complete-conversation rule requires an odd count. That makes seven the largest accepted conversation length under this version. A configuration number alone is not the effective accepted boundary; the predicates compose.
Each message is limited to 1,500 characters, total conversation content to 6,000, and both incoming and upstream request bodies to 24,576 bytes. Character limits do not replace byte limits. Unicode, JSON serialization and the server prompt all contribute to the actual payload crossing the network.
Keep inbound privacy separate from displayed wording
A closed output catalog prevents arbitrary generated prose from reaching the visitor through this response path. It does not prevent a visitor from typing a secret into the input.
Our deterministic input refusal catches recognizable credentials, confidential requests and instruction-override attempts before dispatch. That is useful early refusal. It is not a complete sensitive-data detector, and a missed secret can still travel to the configured model processor.
The interface therefore tells visitors not to share confidential information. The public endpoint has no account lookup, private documents, repository access or business tools. Removing those data paths is more dependable than asking a public model to remember that it should not use them.
This is where I resist a common shortcut in assistant design. A reassuring output cannot prove the input was safe to send. Input inspection, destination eligibility and retention conditions need their own controls before transmission. Rendering approved wording afterward does not undo a disclosure upstream.
The retained request builder asks the provider router for collection-denying, zero-data-retention routing, required parameters and no provider fallback. These are configured routing requirements in this source snapshot. They are not proof of every provider's behavior or a claim that operational metadata disappears.
The server chooses the model from a reviewed allowlist. In the retained snapshot it contains openai/gpt-4.1-nano and openai/gpt-4o-mini. Those names document the implementation we exercised; they are not a current model recommendation or a price-performance benchmark. No live model invocation is part of this article's experiment.
Budget the anonymous endpoint before dispatch
A public guide can consume money even when it cannot take business actions. We require admission before the upstream call. The pure pipeline tests provide a mocked admission dependency so we can prove a denied or failed admission never reaches the mocked provider.
The configured application allowance reserves 10,000 microdollars, or one cent, per admitted call. The daily allowance is 3,000,000 microdollars, or three dollars. Dividing the allowance by the reservation gives at most 300 such reservations, even though a separate outer call-count ceiling is 600.
The same source sets six calls per client in the rolling minute and forty per client in the UTC day. These are configured limits and derived admission arithmetic. They are not observed traffic, actual spend or provider invoice totals.
The admission source puts its conditions and insertion in one SQLite statement. That avoids treating a preceding count query as a reservation. The runtime still needs the intended D1 schema, trusted ingress identity and actual integration behavior. The public-pipeline suite uses mock storage admission; it does not certify D1 concurrency.
The route derives connection identity from the edge-provided connecting IP and rejects a missing or invalid identity. It deliberately ignores a client-chosen forwarded-for substitute. Moving to another ingress requires replacing that trust contract, not copying the header name and assuming the same producer exists.
A daily keyed HMAC represents the connection for admission. That reduces direct identifier retention in the reservation table. It does not make the endpoint anonymous against every observer, and the trusted edge still has its own network view. I keep that privacy claim narrower than the implementation detail.
After reservation there is exactly one upstream fetch attempt. A timeout or disconnect can leave the provider's execution unknown. The application does not automatically retry or refund that reservation. This is a conservative public-service allowance, separate from our richer financial ledger and supplier usage reconciliation.
Fail visibly when the selected route is unavailable
The pipeline has explicit limits around upstream work: a 512-token completion ceiling, a 32,768-byte response ceiling and a configured 20-second upstream timeout. Incoming-body and admission timeouts are separate at five and three seconds.
These bounds constrain different resources. A response size limit needs to apply while reading the body, even if the upstream omits or lies about Content-Length. A timeout needs to cover the remaining response read, not merely receiving headers. A valid HTTP 200 can still contain an error envelope or an incomplete completion.
We reject incomplete, tool-bearing, malformed and oversized responses. A provider refusal becomes the fixed public refusal. Upstream errors remain opaque to the visitor rather than reflecting a provider body that might contain operational details.
There is also a route-selection trap when multiple execution backends are available. The pure pipeline accepts an injected model runner for a separate runtime path, but the retained production route wires only the server-side OpenRouter key. A configured OpenRouter failure does not quietly fall back to that alternate runner.
That distinction belongs in the deployment review. A helper supporting a seam is not evidence that the deployed route exposes it. Conversely, an alternate backend must not bypass a configured route's model allowlist or privacy constraints merely because it can return an answer.
The retained owning suite exercises these choices with mocked responses. It checks configured-route priority, no silent fallback, invalid-model refusal, cancellation, opaque failures and exactly one fetch after a timeout. That gives more useful evidence than a happy-path answer from a single model.
Add authenticated reads through a new contract
A signed-in setup assistant needs a different capability matrix. The architecture permits bounded reads of settings and usage aggregates only after current organization and object authorization. Public visitors receive none of those account capabilities.
The proposed v1 assistant boundary still exposes no business-mutation execution. It can prepare a setup preview, explain selected diagnostic fields or draft a support ticket. The user or operator applies the result through an ordinary authorized product surface.
Secrets remain outside the assistant's read surface. Provider key values, browser cookies, recovery keys and raw private prompt bodies are excluded. An operator role does not automatically grant access to every customer's content; reads stay assigned-case and role scoped.
That boundary makes a preview an object we can inspect. It should show intended destination, exact configuration, selected adapter and remaining manual steps. Generating that object does not authorize applying it. A later execution feature needs an action contract tied to the exact subject the person reviewed.
A consequential agent needs another admission path again: current identity and rights, supported action semantics, bounded payload, approval where required, stable operation identity, fencing and an effect receipt. A tool title or model-selected function name cannot supply those properties.
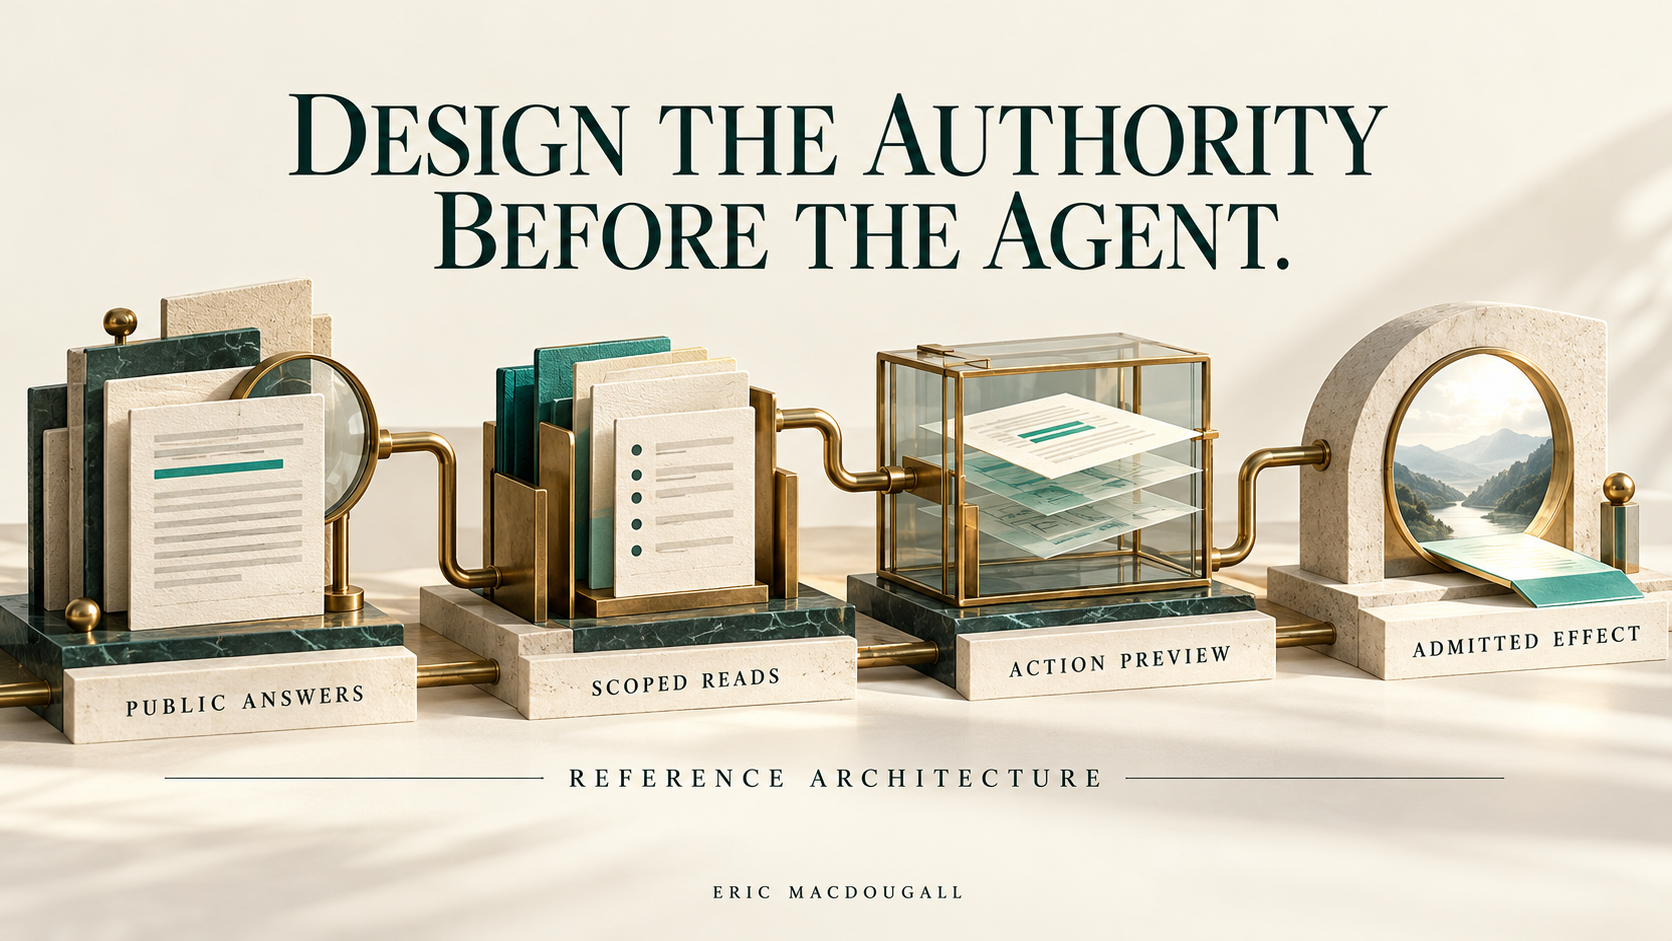
I treat those stages as separate product decisions. Public answers can be useful with no private data. Scoped reads can help without writes. A preview can help without execution. Each step earns its additional authority through a mechanism and an acceptance test rather than inheriting it from a familiar chat interface.
Test the boundary independently of model behavior
The source-bound exercise calls the actual request, history and output helpers. It sends model-shaped objects directly to the guard, including extra prose, unknown IDs, prototype names, duplicate facts and malformed refusal selections. The model does not need to cooperate for us to test those cases.
Three author negative controls change the copied source: replace server wording, remove catalog ownership, and remove role checking. Each makes the exercise fail. That establishes that the checks can detect those particular missing properties; it does not substitute for a blind reviewer's fault model.
The owning 28-test public-pipeline suite also runs without real credentials, network requests or D1. Its original TypeScript loader could not start on this checkout because the dependency was absent. I retained that failed result, then changed only the fixture loader to use Node's built-in type transformation. The test bodies are unchanged and all 28 pass.
For a live launch I still want the actual ingress assumptions, model configuration, provider response, durable admission and browser path verified together. Local mock success cannot promote those missing observations into a deployment result.
Separate the evaluation denominators
I would evaluate the selection model on a labeled set of public questions, including ambiguous requests, unsupported follow-ups and requests that look technical but are covered by the approved brief. Count relevant accepted selections, useful refusals and irrelevant allowed selections separately. A refusal that protects the content boundary can still be a poor user experience when the catalog contains a good answer.
The runtime protocol has another denominator: malformed selections and unapproved output shapes. Those can be exercised directly without paying for a model invocation. The ingress and admission paths have their own cases: missing trusted identity, denied storage admission, slow bodies and unknown upstream completion. Combining all of these into one success percentage would conceal which owner needs to improve the system.
This is also how I would compare models. Hold the catalog, labeled questions, server guards and destination policy constant. Measure relevance, refusal quality, latency and accepted outcome cost. The current offline exercise supplies no model ranking because it never invokes those models.
The product decision I would repeat
Start by deciding which authority the product actually needs. For a narrow public guide, I prefer a reviewed catalog and model selection over an open-ended promise generator. I can measure relevance separately while preserving a deterministic output boundary.
For an authenticated assistant, make authorized reads and previews explicit. For an agent that can change the world, design the action admission, effect identity and recovery path before enabling the tool. Keep the UI familiar if that helps users, but make the backend trust contracts change with the capability.
Take one answer in your own system and trace its source. Then take one proposed action and trace who can admit it. The useful architectural boundary is where the model's suggestion becomes server-owned data or a protected effect.
How this was verified
Five pinned source snapshots cover the public policy, admission source, route, owning tests and assistant architecture. The original source-bound 27-case exercise checks 31 approved facts and all 4,495 unordered three-fact combinations; maximum combined length is 1,313 characters. Three author source mutations fail. The retained owning suite passes 28 tests using mocks and a documented loader-only adaptation after the original dependency failure. No live model relevance, detector-completeness, D1-concurrency, current API-pricing or deployed assistant-plane claim is made.
The independent source-blind review caught 18 of 30 non-equivalent broken variants, with two additional variants proven unreachable under the frozen catalog and exact-key guard. I preserved that result and expanded the exercise from 27 to 44 cases, including the real request handler with fake admission and fetch services. The author replay catches 30 of 30 on the same set; this is a same-set follow-up, not a fresh independent score. No real provider, network or database was used.