
Where JEV earned a decision—and where we replaced it
JEV matched 87 of 88 labels in one of our historical decision benchmarks. That did not make “send uncertain cases to a stronger model” the right next step.
When I recomputed the eight low-confidence cases, the Sonnet fallback introduced two decisions in the costly direction: work labelled as needing a tracked lane was classified as direct action. A deterministic lane default introduced none of those errors. It matched fewer labels overall because it deliberately sent one additional item through the tracked process.
That is the useful story behind our JEV work. We used a fast decision model across routing, review, attention and product-supporting workflows. We made the available choices depend on current facts. We also replaced some model selection with deterministic ladders and kept other uses in shadow or behind measured eligibility.
The architecture question was never simply whether JEV was good. It was which decision a model should own, which alternatives it could choose, what uncertainty should trigger, and which invariant must survive every fallback.
Start with an inventory of decisions, not one model toggle
The central harness registry snapshot contains nineteen points: sixteen base points, two model-routing overlay points and one later attention point. Sixteen are configured live, two off and one shadow. Those are configuration counts, not a census of model calls actually executed.
The base vocabulary spans lane routing and intake, launch checks, reviewer findings and post-review action, release intake, needs/cap/stall cards, coordinator severity and deduplication, owner-ask detection, responder claims, host placement, and the off-by-default customer and child-safety entries. The overlays add author-model, review-model and attention decisions.
A separate product helper has its own point vocabulary, including release-note suppression and a ship-or-refix registration. I do not merge those registries into one deployed feature list. Registration can precede a caller, a point can remain off, and a caller can preserve the legacy result regardless of a model answer.
That distinction matters in the author router. Its configuration can still name a live JEV point while a higher-precedence deterministic ladder returns before that point is asked. A dashboard listing model configuration would miss the effective decision owner.
For the article I built a static callsite inventory and followed the dynamic wrappers separately. Literal-call scanning found fourteen central point names; model selection and needs-card classification also use computed point names. Static matches identify source locations. They do not establish runtime activation, call volume or accepted outcomes.
“Dynamic potentials” describe two different contracts
The first contract is loading decision configuration without rebuilding every caller. Our engine reads a base registry and versioned overlays. Each point declares a provider, model, mode, privacy class, thresholds and a fallback chain ending in the legacy path.
The second contract is constructing the choices for this particular item. A host decision should consider eligible hosts. An attention decision should receive the actions its deterministic rules permit. A model-routing decision should consider the relevant model vocabulary and the caller's availability or reviewer restrictions.
These are related but different. Adding a configuration entry does not authorize a new executable action. Supplying a choice schema does not establish that the action belongs in this item's candidate set. A model's confidence does not repair either boundary.
Our attention guard makes the item-specific restriction explicit:
if point == "attn-decision":
    allowed = tuple(
        str(c) for c in (state.get("candidates") or ())
        if isinstance(c, str)
    )
    return answer if answer in allowed else legacy
This is the actual guard shape, with line wrapping adapted for reading. If the answer is outside the offered candidates, the existing decision remains. An empty attention candidate list does not become an invitation to invent a new action.
That is more useful than asking a model an open question about what the fleet should do. The code computes a bounded decision opportunity; the model helps inside it.
A candidate is not a reservation
There is an important limit to the word eligible. A selection made from a resource snapshot is not a reservation of the resource. Capacity can change between observation and launch, and different layers can use fallback vocabularies for planning.
The model-routing guard has a fixed five-name vocabulary in this source version. If its candidate list is absent or empty, it falls back to that vocabulary. The router also has availability fallback behavior. Therefore this helper alone does not prove that a selected model currently has a free execution slot.
That is why I keep selection and admission separate. The router proposes a route under its policy. The launcher and account or capacity controls own whether that route can actually start. A downstream admission check must not be replaced with “the model picked it.”
Host placement has additional deterministic restrictions. A hard-local requirement wins. A host below its disk floor cannot be selected through the model answer. An unavailable remote host preserves the fallback. An existing hold stays a hold.
The design lesson is to name what each candidate set means: allowed by action policy, plausible for planning, observed available, or reserved for execution. Those are different facts with different validity windows.
Registry growth needs compatibility boundaries
Dynamic configuration also introduces a distributed-systems problem: processes can run different code versions while reading changing files.
Our engine validates the registered point set. The source documents an earlier compatibility failure when a new point in the base registry met older imported code that did not recognize it. The response was to keep newer point families in separate overlays, read only by code that knows them.
The base registry remains the base contract. The model-routing overlay contains only author-model and review-model. The later attention overlay contains only attention decisions. A missing overlay leaves those newer points unconfigured; it does not require the base reader to accept arbitrary new names.
I exercised the actual configuration methods against owned JSON fixtures. With both overlays, the reader returns nineteen points. Remove the model overlay and it returns seventeen. Remove both and it returns the sixteen base points. Unknown base entries, wrong overlay entries, invalid modes, unpinned model values, malformed thresholds and fallback chains without the legacy terminus are refused.
A separate check rewrites a fixture's mode and reads it again. The actual reader sees the new mode without importing new code. That demonstrates rereading behavior; it is not proof that a running production process has selected the intended root, reloaded the file or applied a new policy.
The root matters too. Some helpers accept environment-selected roots or preserve older default paths. “The file exists here” is not sufficient evidence that the worker reads this copy. Activation needs a runtime receipt.
Where we replaced a model question with a rule
Our model router records several generations of policy in one source lineage.
The earlier JEV route chose an author or reviewer from candidates, with deterministic fallback and escalation floors around it. A later rule routed suitable first-round medium work to a whole-task Luna session. Then the R113 build ladder took precedence for unpinned authoring: start low and move up after failed review. In that branch, JEV is not asked.
The later R312 author ladder adds reviewed-attempt proof. A lane name or a request for a more expensive model does not establish that the previous tier was actually tried and reviewed. The router derives the next tier from the recorded attempt history and the ladder contract.
These are concrete examples of taking a decision back from a model. We did not need an additional classifier to answer a question the recorded workflow state could settle. The choice became “which rung follows from this history?” rather than “which model feels appropriate?”
There is still judgment elsewhere. An explicit pin can matter. Reviewer-family restrictions and safety-lane rules can matter. Availability can change. The important point is which owner takes precedence for which decision, rather than whether the system contains JEV somewhere.
The preserved Git history includes restored source and later changes. The source records earlier owner decisions. I keep those dates distinct from claims about when every worker activated a policy. Code history, intended policy and observed execution are separate evidence layers.
Where we kept JEV, but made eligibility local to a class
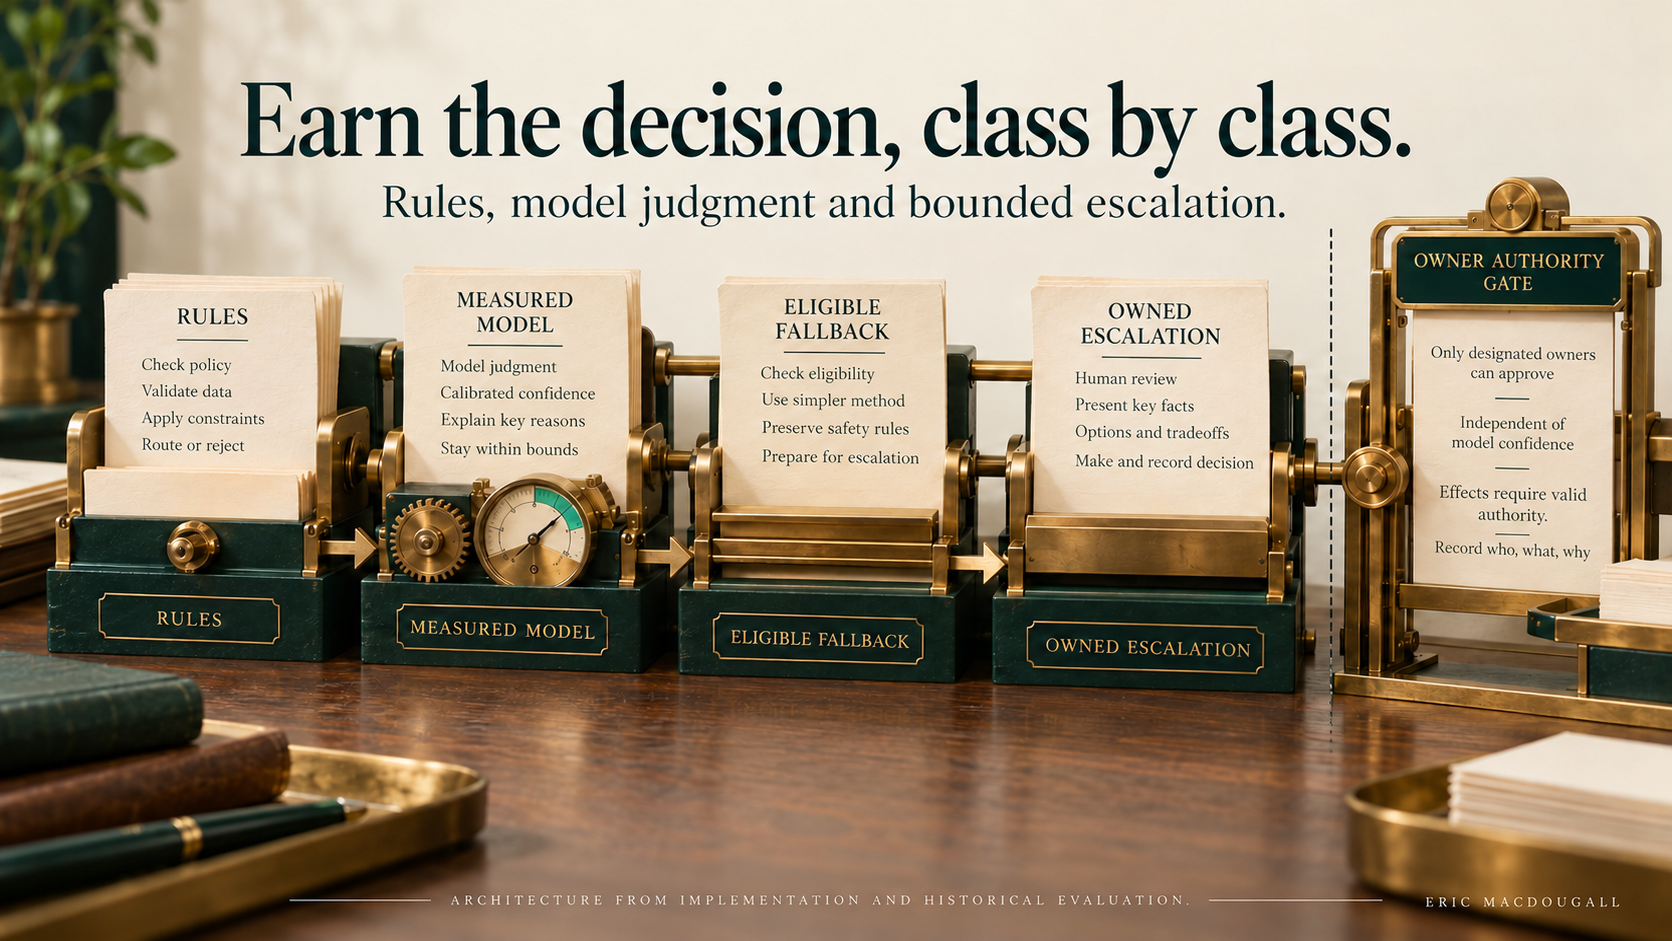
Attention decisions use a different pattern: deterministic rules first, measured model judgment for the ambiguous remainder, then a qualified fallback or an owned inbox route.
The October 16 reliability snapshot contains 3,463 labelled items across 113 classes. It enables JEV for one class and Gemini for none. The configured promotion bar is at least 95 percent agreement on at least thirty answered samples at a selected confidence threshold.
The enabled class is queue-auditor/queue-receipt. Its recorded JEV-v2 sample has forty answers matching forty labels at the selected threshold. The class contains 307 labelled items overall. Forty replay answers are not 307 independent successful live actions.
The label construction is also material. Some labels come from deterministic decisions; others come from mapped operator acknowledgment notes. That can measure agreement with the existing policy and operator behavior. It is not an independent proof that every classification produced the best business outcome.
The attention layer therefore does not treat a global model reputation as permission to automate every class. Unmeasured lane classes are not asked in this escalation path. Other attention classes can remain shadow observations. A model step needs its own measured eligibility and budget, and owner-only work remains owned work.
This is the useful version of self-improvement: accumulate evidence, propose a bounded change, test the class, then promote or roll back under a fixed authority contract. A score should not write itself new capabilities.
Low confidence and provider failure are different events
Our source contains more than one escalation mechanism, and flattening them into one chain would hide important behavior.
The central decision engine has a historical Gemini 3.1 Flash-Lite fallback for failed JEV calls. A low-confidence JEV answer is not classified as provider failure and does not automatically enter that fallback.
The attention layer has a separate measured per-class chain. JEV can be observed in shadow; its answer can be used only when that class is enabled and clears its measured threshold. A Gemini step is used only for an eligible class and within its caps. Otherwise the item goes to the inbox with the chain recorded.
The work-intake path also preserves deterministic restrictions. Its legacy JEV helper turns an unsure route into a tracked lane. A later decision wrapper cannot turn an already-required lane into direct action. The surrounding force-lane policy remains another independent restriction.
Those differences are deliberate contract choices. A timeout may justify trying another provider under the same authority. Uncertainty may justify preserving a safe baseline or asking an owner. Neither event should silently widen the candidate set or erase a required review.
The benchmark that changed how I think about fallback
I recomputed the historical eighty-eight-item set from raw rows rather than copying its report. The labels cover thirty-four routing items, twenty-eight ask-detection items and twenty-six reply-classification items. Each model has one recorded run per item.
| Historical route | Label matches | Median elapsed time | Cost per 1,000 decisions and basis |
|---|---|---|---|
| JEV | 87/88 | 140 ms | $0.0179, input-token estimate at the script's historical rate |
| Luna | 86/88 | 3,561 ms | $0.438, historical token-priced estimate |
| Haiku, clean CLI run | 85/88 | 5,553 ms | $20.65, reported Claude CLI total-cost field |
| Sonnet, clean CLI run | 84/88 | 3,786 ms | $49.40, reported Claude CLI total-cost field |
This is not a like-for-like direct-API price table. The Claude runs include coding-harness overhead, including cache behavior and a large fixed prompt. The JEV and Luna figures are token-priced estimates, not reconciled cash invoices. The model labels and rates belong to the historical experiment; they are not current pricing recommendations.
The fallback subset is more interesting than the overall ranking. Eight JEV answers were below the benchmark's 0.8 threshold. Counterfactually replacing those answers with the same-item Sonnet results yields 84/88 overall and two lane-required items called direct. Haiku fallback yields 86/88 with one such directional error. Luna fallback and the deterministic lane default both yield 86/88 with none.
The deterministic default sacrifices a label match by choosing more process. That can be an appropriate tradeoff when the loss from bypassing review is larger than the cost of one unnecessary lane. A different product can choose a different loss function, but it should choose explicitly.
Eight escalations and authored labels cannot establish a universal model hierarchy. A disputed label appears in the source material. The counterfactual assembly is not a randomized live trial. It does establish that “stronger fallback” and “safer decision under our policy” are not interchangeable claims.
Preserve one-way controls around probabilistic advice
Several implementations use JEV to add caution rather than remove a deterministic restriction.
Reviewer findings can be upgraded to blockers; existing blockers cannot be downgraded by the provider. Post-review advice can request another review or an owned escalation. A model answer cannot invent shipping or parking authority. An inconsistent or provisional result cannot become a clean pass through confidence alone.
Release-note suppression is another useful example. The product wrapper keeps its existing regex exclusions. JEV can add semantic suppression. Missing helper, missing key, timeout or malformed output leaves the existing decision in force. The add-only property belongs to the composition of wrapper and helper, not merely the model's boolean output.
That distinction prevents a common overclaim: a typed answer is valid data, but the caller decides what it may change. Even a pure guard does not own the whole workflow. The current urgency field, for example, is classification rather than a monotone risk maximum. Effect authority remains elsewhere.
For a fallback review, I ask which direction each field may move. Can a provider add a hold? Remove a hold? Change exact event identity? Replace an approver? Choose a repair engine? Publish? The answers should be visible in code and acceptance cases.
Give each decision an owner, a loss function and an exit
My practical template is one row per decision point: source facts, candidate owner, model role, deterministic invariant, uncertainty route, provider-failure route, final effect owner, evaluation denominator and rollback condition.
Use a model where interpreting uncertain evidence improves the decision. Use a rule where recorded state already determines the next step. Use a stronger model when its measured behavior on the relevant error class justifies the extra cost and delay. Preserve an owned escalation when the evidence cannot support automation.
The article's offline guard exercise has sixty-four cases. The registry exercise has twenty. Both execute actual source bodies with explicit local fixtures and no model, network or database calls. They make the contracts inspectable; they do not certify the live fleet.
Pick one decision your agent system currently delegates to a model. Write down the costly direction of error, then replay the fallback against that objective. Also inspect whether the live configuration is even reached. You may find that the best improvement is a better model, a smaller candidate set, or a deterministic question you no longer need to ask.
How this was verified
The source packet retains file hashes, exact guard/configuration excerpts, raw benchmark hashes and recomputed denominators. Historical registry and reliability snapshots are separated from runtime activation. Benchmark costs distinguish CLI report fields from historical token-priced estimates; no invoice or current-price claim is made. Source history documents policy precedence, while full deployment and removal receipts remain a separate operating-history check. No JEV or fallback API was called for this research.