
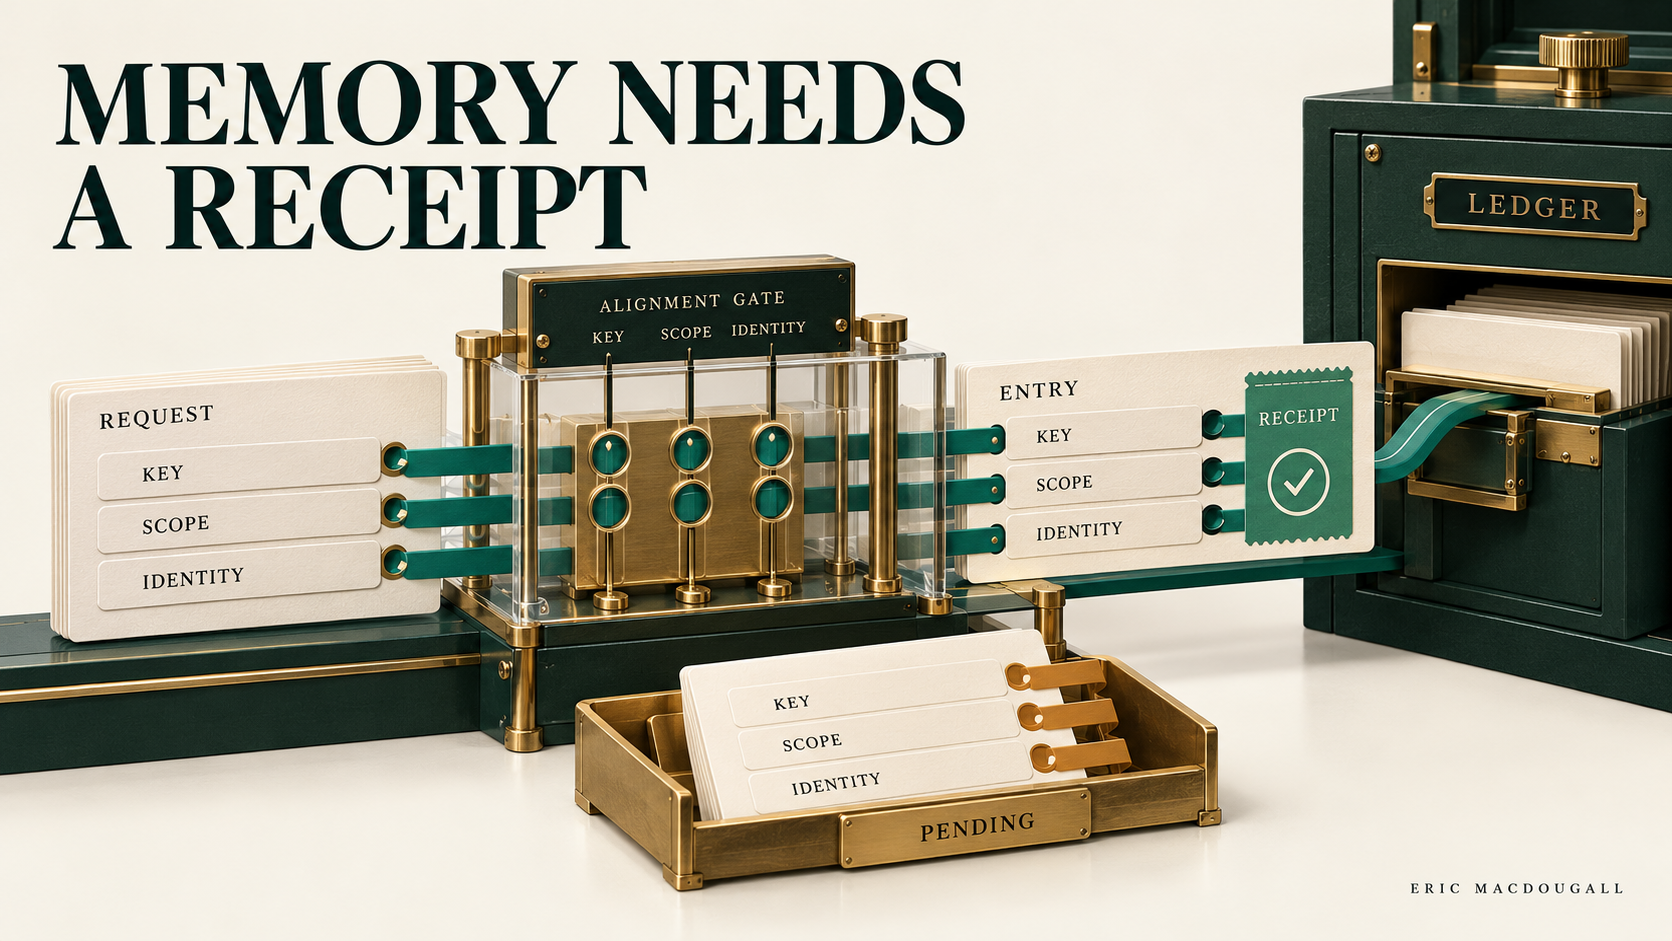
Memory success has to confirm the requester, address and receipt
The owning suite passed. Three planted faults still survived it.
That is the result I keep coming back to in our memory-tools work. The retained frozen review shows 113 owning checks passing, with 18 intentional nested-control skips. A separate six-probe suite caught all seven deliberately broken variants. The owning suite caught four of those seven.
The three differences were useful: a shared catalog leaking a machine grant across requesters, a memory-list operation entering the successful-write ledger, and an HTTP exception being represented as success. Each sits between components that can look reasonable when tested alone.
I built the memory path around those boundaries: who may discover and call a tool, which address a successful response confirms, what counts as failure, and which results suppress another write. The resulting code is a tested source candidate; the historical handoff still requires parent-owned review before activation.
The broader lesson is that memory security includes the whole write-confirmation and replay path. Storing the right text is one part of it. Knowing whose memory was written, whether storage actually completed and whether another attempt is safe determines what the agent can responsibly say afterward.
Memory changes the next turn
A remembered item can outlive the conversation that produced it. It may influence a later answer, another model candidate or a recovered turn. That persistence makes the write a consequential operation even when the value looks like an ordinary preference.
I want the system to preserve the difference between a requested memory, a proposal waiting for approval and confirmed storage. A model saying it will remember something does not establish the third state. Neither does a transport response that happens to contain an entry-shaped object.
The runner has three memory tools: remember, recall and list_memories. Only remember belongs to its write classification. Reads still use requester-bound access, but their results do not belong in the ledger that suppresses repeated successful writes.
That classification is part of the behavior. Treating a read like a completed effect can prevent a later read from observing current state. Treating a write like a read can repeat it after candidate failover or turn requeue. The distinction needs a behavioral test, not just a comment beside a tool name.
I also keep retrieval and authority separate in the design. A remembered instruction should not create a new permission. The runner's requester catalog and server-side request context remain responsible for tool access; a memory value cannot substitute for them.
Discovery is requester-specific
The runner lists tools for the turn's delegated requester token. The available catalog can differ between people. Memory grants are requester-specific, and machine tools may depend on a separate grant.
That makes a shared catalog cache a security concern. A list that was valid for one requester may advertise capabilities another requester does not hold.
The code keeps a shared fallback only for eligible adjacent tools. It deliberately excludes memory tools and names beginning with machine_ when storing that fallback. If a fresh catalog request fails, the fallback cannot transfer those requester-specific capabilities into the next turn.
The call path adds another check. For a memory tool, being in the runner's broad allowlist is insufficient: the tool must have appeared in the catalog listed for this requester. Otherwise the call returns an unsuccessful-storage result before dispatch.
This does not replace service-side authorization. A catalog is a view of available capabilities, and it can become stale. The server still needs to evaluate the actual request with its current authority. The useful local property is narrower: a failed catalog refresh does not borrow a previous person's memory or machine capability.
The fallback also has a lifetime. An absent or expired safe catalog cannot quietly become a successful tool-discovery result. The code uses a one-hour freshness bound for this shared fallback, then propagates failure when no eligible current fallback exists.
Preserve the requester on the transport
The tool wrapper carries a requester-bound turn token through its MCP calls. Its extra-header map starts empty.
The historical source explains an important compatibility detail: the lease's invocation grant was signed for a different persona credential, so combining it with the turn token was refused. The turn token already carries the audience the service derives from the leased turn. Adding a second authority-looking value would not make that request more authorized.
I want this relationship visible in tests. The offline exercise uses the real wrapper and RPC construction with a fake HTTP boundary. It checks the token-specific dispatch, method, endpoint, empty extra map and request shape without reaching a server.
That establishes local forwarding behavior. It does not establish that a production service accepted the token or enforced organization isolation. Those are separate integration observations.
The architecture should make both responsibilities explicit: the runner preserves the intended requester context; the receiving service derives and enforces the allowed operation. A successful test of either component alone does not qualify the entire route.
Confirm the address that was actually requested
A memory address includes more than its key. The wrapper checks the returned key, scope type and agent identity against the arguments it actually forwarded.
Optional values make that last phrase important. A strict tool caller may provide null or an empty string for an optional namespace. The runner removes those unset optional values before dispatch. When agent identity is omitted, the response must confirm the default identity.
Validation against the unnormalized input would create a mismatch between the request sent and the request being checked. The normalization and confirmation need to agree on the same effective address.
The actual predicate checks the decoded result before a memory write can be treated as successful:
if not (isinstance(result, dict) and 'error' not in result and not result.get('needsDecision')
        and isinstance(result.get('entry'), dict) and result['entry'].get('key') == arguments.get('key')
        and result['entry'].get('scopeType') == arguments.get('scope')
        and result['entry'].get('agentIdentity') == arguments.get('agentIdentity', 'default')):
An entry with the wrong scope, identity or key is unsuccessful storage. With a valid requested address, missing and null returned fields are unsuccessful too. A result that still needs a decision remains incomplete even if it contains a matching entry.
There is an important limit to this comparison: the product response does not serialize scopeId. The runner cannot confirm an echoed field that does not exist. That part of isolation remains bound to the requested path and requester token, with enforcement owned by the service.
I would not describe the local address check as complete authorization proof. It confirms the returned fields the contract actually exposes, alongside a transport path whose server must supply the remaining isolation guarantees.
Pending approval is not successful persistence
A response can carry useful information before an operation is permitted to complete. In this path, needsDecision is one such signal.
A useful state table has separate rows for requested, waiting for a decision, refused, unknown and confirmed. The visible answer and the persisted write ledger should agree on that classification; a friendly sentence cannot substitute for the state transition.
The wrapper refuses to treat it as success, including when an entry object matches the requested address. That ordering prevents an approval-shaped response from entering the successful-write ledger merely because some returned fields look right.
The same applies to MCP's error signal and application error objects. The wrapper converts an MCP error into a JSON error result. The memory-specific confirmation then keeps unsuccessful storage in an error envelope rather than allowing a raw message to stand in for a successful write.
The consequence is observable on another attempt. An incomplete write does not acquire the local success receipt that would suppress dispatch. A confirmed write does.
This is why I prefer tests that check both the visible result and the ledger. A refusal message can look correct while the implementation records success underneath it. The next turn then behaves as though the memory exists, even though the current reply admitted that storage was incomplete.
Error serialization participates in the state machine
The runner bounds tool output to 24,000 Python characters. That is a code limit on characters, not a claim about a 24-kilobyte transport envelope.
A subtle dependency appears in the write ledger: it determines failure by parsing the tool result as JSON and looking for an error field. If parsing fails, the generic ledger path does not mark the result as failed.
That makes naive truncation dangerous. Cutting a large error object at the output bound can produce invalid JSON. The producer meant failure; the consumer sees a result it cannot parse and follows its non-failure path.
The memory repair preserves a valid failure envelope. It serializes the unsuccessful result, checks its size, bounds the diagnostic detail inside the object and serializes again before the final output limit:
out = json.dumps(failure)
if len(out) > 24_000:
    failure.update(result=out[:2000], truncated=True)
    out = json.dumps(failure)
The preserved error field is consequential. It lets the downstream ledger continue to recognize failure even when the original tool output was oversized, malformed, wrong-address or approval-pending.
This is a narrow repair for the memory wrapper's unsuccessful results. The generic ledger's treatment of arbitrary invalid JSON remains a separate concern. I do not turn the memory fix into a claim that every tool has a safe failure format.
The integration lesson is to inspect the producer and consumer together. A size limiter is not merely a presentation concern when another component uses the serialized shape to decide whether an effect completed.
Deduplication begins with confirmed success
For a write, the turn state hashes the turn ID, tool name and serialized arguments. A confirmed result is cached in the current state and its digest is added to the persisted write ledger.
The same state can then return the cached result without another dispatch. A reconstructed turn state can recognize the persisted digest and report that the exact change was already made for that message.
The offline exercise checks those behaviors using real ledger files under owned scratch and a fake HTTP boundary. It also checks the other branch: wrong-address results, approval-pending results and transport exceptions leave both the in-memory and persisted success collections empty across repeated states.
Those local properties do not provide distributed exactly-once execution. There is still a window between a remote write completing and its local success ledger being persisted. A process failure in that window needs an operation identity and reconciliation strategy at the service boundary if repeated effects matter.
The current digest also uses the arguments passed to the turn-state method, before the tool wrapper normalizes optional values. Semantically equivalent argument forms need not acquire the same local digest. I would keep that distinction visible when designing stronger idempotency around the remote operation.
A ledger is useful because it preserves evidence of confirmed work. Its guarantee has to be described at the actual boundary it controls.
Reads need fresh execution opportunities
recall and list_memories are excluded from the successful-write classification. That allows repeated reads through the ordinary logging and call path.
This matters across both candidate failover and reconstructed turn state. A read that happened earlier should not be replaced by a generic note saying that the exact change was already made. There was no change to suppress.
In the fresh offline exercise, the same and reconstructed states perform both read operations repeatedly. All six fake dispatches occur; none enters the write collections. A corresponding confirmed write dispatches once and is then recognized by the local ledger.
The distinction is simple to state and easy to lose inside a broad “all tools should be idempotent” rule. The useful question is which operation identity and result freshness the caller needs. A read and a write can need very different replay behavior even when they share the same transport wrapper.
Independent review changed the observations
The retained review is valuable because the independent probes challenged component interactions the owning suite did not distinguish.
On the frozen reviewed source, the baseline owning run reported 113 passes and 18 intentional nested-control skips. The independent baseline reported six passes. Both baselines exited successfully.
Across seven deliberately broken variants, the owning suite detected four; the independent probes detected seven. The three owning-suite survivors concerned machine-grant fallback caching, a list operation classified as a write and a transport exception becoming success.
These are historical results with a fixed source and mutation cohort. They do not estimate a general defect-detection rate, and the six independent probes should not be compared with 113 owning checks as though a smaller count inherently means a better suite.
What matters is the discrimination. The independent tests made a different set of hypotheses observable. That is the reason to preserve the original suite and add an independent challenge, rather than assuming more cases written from the same implementation perspective will cover every important interaction.
The current article exercise is another artifact. It extracts nine complete definitions verbatim from the source and supplies explicit imports, empty local-module registration, fake HTTP responses and owned ledger storage. It gives readers a reproducible local path through the mechanisms without starting the runner or contacting a model.
Activation is another boundary
The source handoff records the memory work as author-ready for parent-owned review, with activation still requiring a separate review and bounded memory probes. I keep that status attached to the technical account.
A locally correct write wrapper does not establish that the running service is using it. A successful fake requester does not establish that a real customer can access only the intended namespace. A local ledger reload does not establish recovery across every daemon or deployment failure.
For an activation decision, I would want the exact installed source, requester-bound discovery, remote authorization, successful storage, same-thread recall and new-thread recall exercised through the intended route. Failed and approval-pending storage should be observed alongside those positive cases.
That is the proposed acceptance path. The retained offline results qualify the source mechanisms; they do not silently complete the deployment work.
Trace the success claim
A useful way to examine an agent's memory system is to follow a single sentence: “I remembered that.”
Which requester discovered the tool? What normalized address was sent? Which returned fields confirmed it? Did the result still require approval? Did its error shape survive the output bound? Which confirmed receipt entered the ledger? What happens if the process stops before that receipt is saved?
Those questions connect access control, transport semantics, serialization and recovery. They also give the reviewer concrete failure hypotheses instead of a general request to look for memory bugs.
Take one memory write in your system and trace that success claim across every component that interprets it. Then deliberately break one boundary and check that the visible reply and the persisted state agree about what happened.
How this was verified
The runner source is pinned at the integrated candidate and is byte-identical to the retained reviewed worker. Historical review arithmetic is recomputed from retained receipts: owning 4/7 and independent 7/7 mutations detected, with successful baselines. Those results are not fresh executions. The current offline exercise uses nine verbatim source definitions with fake transport and real local ledger files; it makes no remote model, database or network calls. Source qualification, requester-service integration and activation remain distinct. No deployed memory guarantee, generic invalid-JSON safety or distributed exactly-once claim is inferred.
The fresh independent review of the original 37-case exercise detected 17 of 30 planted faults (control exit 0). After reading those gaps, I expanded the exercise to 55 cases. An author-run follow-up detects all 30 from that same set, with syntax checks passing and restored control exit 0. This is a same-set follow-up, not a new independent score; peer confirmation is retained with the exact source and exercise identities. The original exercise and receipt are retained. The generic ledger characterization intentionally preserves its current behavior: malformed non-memory write output is recorded as success. The memory wrapper provides the narrower parseable-failure guarantee described here.
Peer replay confirmed 30/30 on the same set with control exit 0 and unchanged source hashes. This remains a same-set follow-up; the original independent result is retained.